

We swapped our LLMs for Jev. It's 39% cheaper.
Explore with AI
We’re building an always-on on-call agent, which constantly makes decisions, for example:
- how severe is this issue?
- should we be pro-active on this slack thread?
- have we seen this incident before?
Up until last week, we’ve been using LLMs for these tasks. As soon as we got access to Jev this week we started experimenting with it.
What is Jev?
Jev is a decision model from TypeSafe AI. It doesn’t generate text: it answers questions about your data with typed values and calibrated probabilities. TypeSafe pitches it for “smart if-statements”, the classify, route and score steps where hand-written logic is too brittle, and quotes 70 to 500 ms per response with free output tokens. Our agents make those decisions all day, so we put it in production.
How it works
A request has two parts: the state, which is the text or JSON you want a decision about, and the questions you want answered. Each question has one of three types:
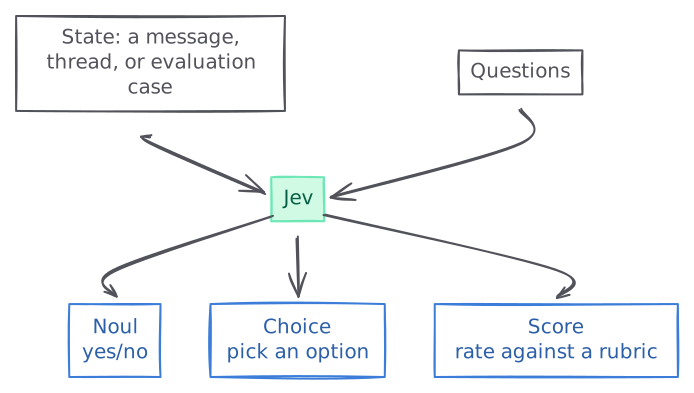
- Noul returns the probability of
yes. - Choice selects one of the provided options.
- Score returns a probability-weighted value across an ordered rubric.
Use-case 1: Routing, or when should the agent respond?
Our agents are pro-active on Slack and Github. They will respond to Slack messages or Github comments if they have a meaningful insight to provide to the user. The agents need to act when a user requests it, without overreacting to every event. This is a perfect use-case for Jev’s Noul questions.
- Comments on PRs our agents submitted: a reviewer asking for a change wakes the agent up. A CI status update or a “thanks” doesn’t.
- Slack channels: the agent jumps in uninvited only when it can clearly help, like a direct infrastructure question. It stays out of humans coordinating with each other.
- Slack threads the agent is in: it answers messages meant for it, ignores humans talking to each other, and leaves when someone asks it to.
Here is an example of a Jev request to determine if an agent should follow up on a Slack message.
{
  "model": "jev-1.13.0",
  "state": {
    "slack_channel": "#Deployment",
    "user_message": "Watch this PR until fully deployed"
  },
  "questions": {
    "respond": {
      "type": "noul",
      "instructions": {
        "question": "Should the agent follow up on this user message?"
      }
    }
  }
}
We ran Jev for about a week and compared with the LLM we previously used for this task.
P90 latency
Cost per 1,000 calls
Routing got 3x faster at P90, from 1.5 seconds to under 500 ms, and the cost dropped by almost half.
Use case 2: Classification, or what does the evidence mean?
We also run a few tasks where the agent needs to classify things into different buckets. For example, based on the provided evidence, should the agent start investigating the issue, should it fold it as related to an existing issue, or is it a duplicate of a previously resolved issue?
A Jev Choice question turns that evidence into one label from criteria we define, and the next step is decided by the label. It looks like this:
We run three classifications this way. Each one uses a Choice question with explicit criteria, and each one replaced a different LLM, so we measured them separately.
Are these incidents related?
When a new incident opens, the agent compares it with existing incidents: do they share one root cause, are they related, or are they independent? This illustrative example shows one candidate; a production call compares several against the same new incident.
{
  "model": "jev-1.13.0",
  "state": {
    "incident": "Checkout cannot authenticate to the database.",
    "candidate_0": "Billing cannot authenticate to the same database.",
    "evidence": "Both services use a credential revoked at 14:00."
  },
  "questions": {
    "candidate_0": {
      "type": "choice",
      "instructions": "How is candidate_0 connected to the new incident?",
      "criteria": {
        "duplicate_same_root_cause": "One underlying problem explains both",
        "related": "Distinct problems share a trigger or blast radius",
        "independent": "No evidenced connection"
      }
    }
  }
}
By switching to Jev for this use-case, we made it almost 8x faster at P90, from 2.9 seconds to under 400 ms, and 27% cheaper.
P90 latency
Cost per 1,000 calls
Why did this PR we submitted get closed?
Our agents submit pull requests to developers, and one of our key success metrics is the merge rate. We need to understand why pull requests get closed such that we can improve the product.
When one of our PRs is closed without merging, the agent reads the reviews, the discussion, and references to other work, then picks the reason: the fix was wrong, a human fixed it another way, the issue was a false positive, the PR went stale, or the behaviour was intended.
By switching to Jev for this use-case, we improved latency to 6x faster at P90, but only 17% cheaper.
P90 latency
Cost per 1,000 calls
How pressing is this pull request?
Before submitting a pull request to developers, our agents need to rank it such that higher severity things rise to the top. For this classification, the agent grades the underlying problem on a ladder from critical to info. It grades current impact, not hypothetical risk.
P90 latency
Cost per 1,000 calls
Switching to Jev here substantially reduced cost: 59% cheaper than DeepSeek V4.1 Flash, and nearly 5x faster at P90.
Jev is faster on every classification. Where it replaced GPT-OSS 120B, the gain is mostly latency. Where it replaced DeepSeek V4.1 Flash, it also cut the bill by more than half.
Use case 3: Ranking, or how important is this cloud resource?
To get the best out of Polylane, teams connect their cloud accounts. We create a context graph of all the cloud resources, such that the agents can quickly understand the relationship between compute nodes, databases, queues, etc.
We have teams on the platform with extremely busy cloud accounts, with 10s of thousands of nodes. Each server, sandbox, database, and queue is a node in our context graph. It’s necessary to rank each of these nodes such that agents know what is critical to your application, and what is essentially “fine” to fail.
We assign one of four priority tiers to each resource: Critical, Standard, Low, or Minimal.
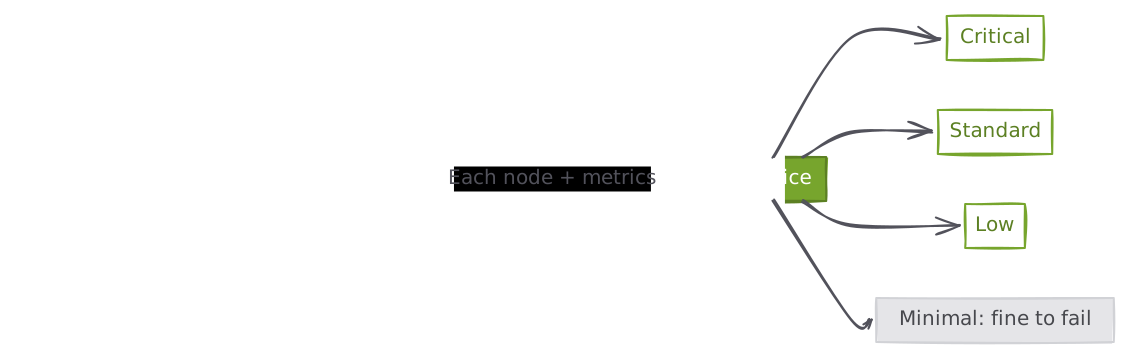
Jev evaluates a Choice question for each resource, with context based on configuration, environment, recent metrics, and dependencies.
{
  "model": "jev-1.13.0",
  "state": {
    "instructions": "Assign importance relative to the other resources in this cohort.",
    "cohort": [
      {
        "id": "database-a",
        "environment": "production",
        "daily_queries": 80000,
        "dependents": 6
      },
      {
        "id": "database-b",
        "environment": "preview",
        "daily_queries": 0,
        "dependents": 0
      }
    ]
  },
  "questions": {
    "resource_0": {
      "type": "choice",
      "instructions": "Assign the importance tier for database-a.",
      "criteria": {
        "1": "Critical: substantial production traffic or blast radius",
        "2": "Standard: active and operationally relevant",
        "3": "Low: limited activity or importance",
        "4": "Minimal: idle or disposable, without meaningful dependents"
      }
    }
  }
}
Ranking is where Jev shines: more than 10x faster at P90, from 5.4 seconds to about half a second, and 34% cheaper. It’s also our highest-volume decision, so it drives most of the overall savings.
P90 latency
Cost per 1,000 calls
Summary
Overall, Jev delivered substantial overall reductions in latency and estimated cost per 1,000 calls:
- P90 latency reduction: 4,752 ms —> 508 ms.
- Cost per 1,000 calls reduction: $0.76199 —> $0.46369.
P90 latency
ms · lower is betterCost per 1,000 calls
USD · lower is betterPer model, Jev is both the fastest and the cheapest: slightly cheaper than DeepSeek V4.1 Flash, and well below both GPT-OSS models.
Swipe to see every point.
Wherever our agents pick from a fixed set of answers, Jev is now the default: it is faster and cheaper on every decision we moved.