 Boris Tane
Fix “Durable Object reset because its code was updated”
Explore with AI
Durable Object reset because its code was updated.A new version of your Worker was deployed, so Cloudflare shut down the running Durable Object and any in-flight request that touched its storage failed with this error. Data already written to storage is safe; only in-memory state is reset. Catch the error, create a fresh stub and retry with jittered backoff when e.retryable is true, and keep the API between your Worker and the object compatible across versions.
On this page
- What “reset because its code was updated” means
- Matching the errors to a release
- Cause 1: a deploy shut down the object during a request
- Cause 2: frequent deploys reset objects again and again
- Cause 3: a gradual deployment assigns the object a new version
- Cause 4: a long-running caller holds on to a stale stub
- Reconnecting WebSocket clients after a deploy
- Confirming the fix during your next release
- Keeping deploys from breaking Durable Object callers
- Reviewing Durable Object changes before they ship with Polylane
- Common questions
This error usually turns up in the Worker that calls your Durable Object, a few seconds after wrangler deploy. A call to the object’s stub, or a storage read or write inside the object, throws. Users see a failed request, a dropped WebSocket or an agent that stops halfway through a task. A minute later everything works again.
The message is telling you that the Durable Object instance your request was talking to was shut down because a new version of the code went live. The data it had already saved is safe. What failed is the request that was in flight at that moment. The fix is to make your callers survive that moment: retry with a fresh stub, keep both code versions able to talk to each other, and reconnect clients.
What “reset because its code was updated” means
A Durable Object is a single instance for a given ID, running somewhere in the world. Cloudflare’s known issues page explains the guarantee behind this error: only one instance of a Durable Object class with a given ID runs at once, and Cloudflare enforces that when a new event starts and whenever the object accesses storage.
When you deploy new code, Cloudflare shuts down the running instance and starts a new one, and new requests go to the new instance. The lifecycle docs say what happens to work that was already running:
- HTTP and RPC requests may finish if they don’t access the object’s storage. A request that tries to access storage is stopped immediately and returns an error, to protect global uniqueness. That error is this one.
- WebSocket connections are terminated, so the new instance can take over.
- Other invocations, such as email and cron, are treated like HTTP requests.
The word “reset” is narrower than it sounds. The troubleshooting page says it refers to in-memory state, and anything already persisted through state.storage is not affected. Class fields, in-memory caches and timers are gone. The constructor runs again on the next request.
Deploys are one of several reasons an object shuts down. The lifecycle docs also list inactivity, Cloudflare updates to the Workers runtime, and runtime decisions about where to host objects. Resource limits are a different failure again. The error handling page notes that an object that exceeds its memory or CPU limits throws an infrastructure exception with .remote set. We wrote up a memory case of our own in how we fixed our Durable Objects memory exceeded errors.
Matching the errors to a release
Before you change any code, check that the errors line up with your deploys:
npx wrangler deployments list
npx wrangler versions list
deployments list shows your Worker’s 10 most recent deployments with their times. Put those next to the times of the failed requests in Workers Logs. If each burst of errors starts within seconds of a deployment and dies out soon after, you have this error’s normal pattern.
To watch it live during a deploy, run wrangler tail in a second terminal:
npx wrangler tail my-worker --format json --status errorwrangler tail shows console and exception logs for requests to both the Worker and its Durable Objects. One catch from the known issues page: enabling wrangler tail or dashboard logs requires a software update, which can itself replace the object. Start the tail before the deploy you want to watch, so starting it doesn’t add a reset of its own.
I built and led the Workers observability team at Cloudflare, and for an error like this the first thing I check is which version served each failing request. wrangler tail takes a --version-id filter for exactly that.
Cause 1: a deploy shut down the object during a request
This is the case the message names. A request was in flight on the old instance, it touched storage after the shutdown began, and the runtime stopped it.
How to tell it’s yours: the errors cluster right after a deploy, they come from the caller side of a stub call (an RPC method or stub.fetch()), and the same request works when you send it again.
Retry with a fresh stub and jittered backoff
The error handling page says exceptions from Durable Objects reach the caller, and that errors with .retryable set to true are suggested to be retried when the request is idempotent. It also warns that many exceptions leave the stub in a broken state, so you should create a new stub for each attempt. Here is Cloudflare’s retry example adapted for an RPC call:
import { DurableObject } from "cloudflare:workers";

async function callCart<T>(
  env: Env,
  cartId: string,
  call: (stub: DurableObjectStub<Cart>) => Promise<T>,
): Promise<T> {
  const maxAttempts = 3;
  const baseBackoffMs = 100;
  const maxBackoffMs = 20000;

  for (let attempt = 0; ; attempt++) {
    // A new stub per attempt: a failed stub stays broken.
    const stub = env.CART.getByName(cartId);
    try {
      return await call(stub);
    } catch (e: any) {
      if (!e.retryable || e.overloaded || attempt + 1 >= maxAttempts) throw e;
      const backoffMs = Math.min(
        maxBackoffMs,
        baseBackoffMs * Math.random() * Math.pow(2, attempt),
      );
      await scheduler.wait(backoffMs);
    }
  }
}

export default {
  async fetch(request, env, ctx): Promise<Response> {
    const cartId = new URL(request.url).searchParams.get("cart") ?? "";
    const items = await callCart(env, cartId, (stub) => stub.listItems());
    return Response.json(items);
  },
} satisfies ExportedHandler<Env>;
Steps:
- Wrap every stub call that can run during a deploy in a helper like
callCart. - Check
e.retryableand stop when it is false. Checke.overloadedtoo: Cloudflare says overloaded errors should never be retried, because retrying worsens the overload. - Make the retried call idempotent. A read is safe. A write such as “add one item” needs a key the object can check, so a retry doesn’t add the item twice.
- Keep the jitter.
Math.random()in the delay spreads retries out, so every caller that failed during the deploy doesn’t arrive at the new instance in the same instant. - Deploy and watch the logs during your next release. Failed requests should turn into slower successful ones.
Cause 2: frequent deploys reset objects again and again
Every deploy with a code update shuts down the objects that are running. If your pipeline deploys on every merge, a busy day means many resets, and requests that cross any of them can fail. Several deploys in a few minutes can keep long-lived objects restarting before their work is done.
How to tell it’s yours: npx wrangler deployments list shows many deployments close together, and the error bursts in Workers Logs line up with each one.
Cloudflare’s gradual deployments page adds a detail that matters here. A Worker bundle typically defines both the Durable Object class and the Worker that calls it, and in that case you can’t deploy changes to one without the other. So a change to a Worker route is also a code update for every Durable Object in the same bundle.
Steps:
- Batch releases. Merge to main as often as you like, and deploy on a schedule or when a set of changes is ready.
- Deploy Durable Object class changes, the
exportsormigrationsentries in your Wrangler file, on their own. Cloudflare says lifecycle changes are atomic and should be deployed separately from other code to limit the blast radius. - Keep the retry helper from cause 1 in place. Fewer deploys means fewer resets, and the helper covers the ones that remain, including runtime updates you don’t control.
Cause 3: a gradual deployment assigns the object a new version
With a gradual deployment, each Durable Object is assigned a Worker version based on the percentages you configured, and keeps it until you create a new deployment. The gradual deployments page says an object is reset only when it is assigned a different version. In Cloudflare’s example that moves from version A to version B in steps, each object is reset once.
How to tell it’s yours: the errors arrive in waves, one per step of the rollout, and each object fails only once per step. Between steps, a new Worker can call an object that still runs the old code.
The known issues page says code changes reach Workers and Durable Objects in an eventually consistent way, so this mixed-version window exists in every deploy. It typically lasts seconds to minutes. With a gradual deployment it lasts as long as your deployment uses more than one version. Cloudflare’s advice is to make the API between your Workers and Durable Objects forward and backward compatible.
Keep the RPC API and storage readable by both versions
- Add, never change. Give new RPC parameters a default, so old callers keep working:
export class Cart extends DurableObject<Env> { // v2 adds currency. v1 Workers still call addItem(sku, qty). async addItem(sku: string, qty: number, currency: string = "USD") { const items = (await this.ctx.storage.get<Item[]>("items")) ?? []; items.push({ sku, qty, currency }); await this.ctx.storage.put("items", items); } } - Ship a new method in one deploy, and start calling it from the Worker in a later one. That way no new Worker calls an old object that lacks it.
- Read old storage shapes as well as new ones. Store a version with the data and upgrade it when you read it:
type StoredV1 = { sku: string; qty: number }; type StoredV2 = { v: 2; sku: string; qty: number; currency: string }; function readItem(raw: StoredV1 | StoredV2): StoredV2 { return "v" in raw ? raw : { v: 2, ...raw, currency: "USD" }; } - Remove old fields and methods only after the version that stopped using them is at 100%.
Cause 4: a long-running caller holds on to a stale stub
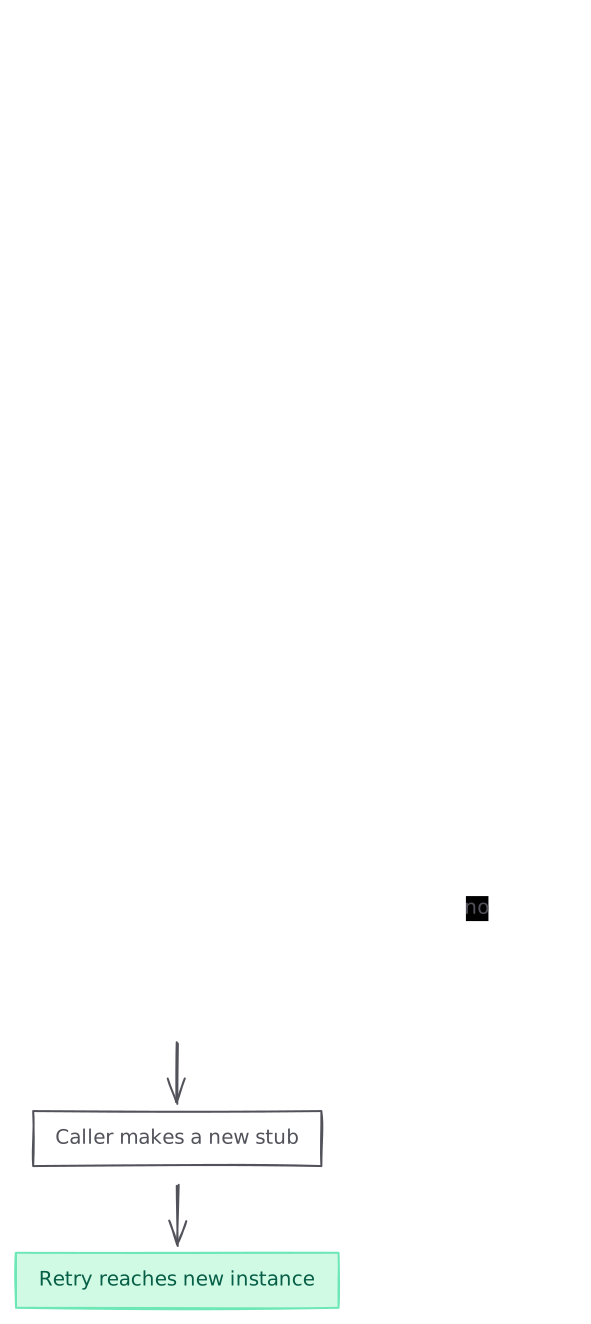
Agent loops, Workflow steps and queue consumers often create a stub once and call it many times. If a deploy lands in the middle, the first call after the reset fails, and the error handling page says every later call on that broken stub fails at once with the original exception. One deploy then fails the rest of the run.
How to tell it’s yours: a long task logs this error, then the same error repeatedly with almost no time between the calls, until the task gives up.
- Create the stub inside the loop, or inside the retry helper from cause 1, never once at the top of a long task:
for (const step of plan) { await callCart(env, cartId, (stub) => stub.applyStep(step)); } - Inside the object, write progress as you go. Durable Objects have no shutdown hooks, and the lifecycle docs recommend writing state incrementally so a new instance can resume:
async processBatch(items: Item[]) { const start = (await this.ctx.storage.get<number>("nextIndex")) ?? 0; for (let i = start; i < items.length; i++) { await this.processItem(items[i]); await this.ctx.storage.put("nextIndex", i + 1); } } - Keep anything the object can’t rebuild in
ctx.storage. In-memory state is discarded on a reset and on hibernation alike.
Reconnecting WebSocket clients after a deploy
Cloudflare’s WebSockets guide is blunt: code updates disconnect all WebSockets, because deploying a new version restarts every Durable Object. A browser or service that keeps a socket open to an object will see it close on every deploy.
- Reconnect on close, with backoff and jitter:
let attempt = 0; function connect(url: string) { const ws = new WebSocket(url); ws.addEventListener("open", () => { attempt = 0; }); ws.addEventListener("close", () => { const delay = Math.random() * Math.min(30_000, 500 * 2 ** attempt); attempt++; setTimeout(() => connect(url), delay); }); return ws; } - After reconnecting, have the object send its current state, read from storage, so the client doesn’t depend on messages it missed.
- If you build on the Agents SDK, its client SDK handles this.
useAgentandAgentClientreconnect automatically with exponential backoff, and the agent sends its current state on each connection.
Confirming the fix during your next release
- Run steady traffic against the Worker. A script that calls the object every few hundred milliseconds is enough.
- Start
npx wrangler tail --format json --status errorbefore the deploy. - Deploy, and watch the tail for the next minute.
- With the fix in place, any reset errors should be caught by the retry helper and end in a successful second or third attempt. Requests that fail outright should drop to zero. WebSocket clients should log a close and a reconnect.
- Check Workers Logs for the release window afterwards, and confirm that no request failed with the reset message.
Keeping deploys from breaking Durable Object callers
- Route every stub call through one retry helper, so new code gets the fresh-stub, backoff and
.overloadedrules for free. - Review API changes for compatibility. A changed RPC signature or storage shape is the change most likely to fail during the mixed-version window.
- Deploy on a cadence, and ship Durable Object class changes on their own.
- Alert on the error count during releases. A spike right after a deploy that doesn’t fall back to zero means a caller is missing the retry.
- Persist as you go. Treat in-memory state as a cache that can vanish at any deploy.
Reviewing Durable Object changes before they ship with Polylane
Polylane links each repository to the Workers it deploys by reading manifest files such as Wrangler files, then reviews every pull request against those live resources and posts a pass or fail comment. It also raises an advisory when a Cloudflare Worker has logs disabled, the gap that leaves a burst of reset errors with nothing to explain it.
Running on Cloudflare? See how Polylane monitors Cloudflare in production.
Common questions.
Does “Durable Object reset because its code was updated” lose my data?
Not the data you already saved. Cloudflare's troubleshooting page says reset refers to in-memory state, and anything successfully persisted through state.storage is not affected. Class fields, caches and anything else you only held in memory are gone, and the constructor runs again on the next request.
Should I retry a request that failed with this error?
Retry when the exception has .retryable set to true and the request is idempotent. Cloudflare's error handling example uses 3 attempts, a 100 ms base delay and a 20,000 ms cap with exponential backoff and random jitter. Never retry an exception with .overloaded set, because that makes the overload worse.
Why does every call fail after the first reset?
You are probably reusing the same stub. Cloudflare's docs say many exceptions leave a DurableObjectStub in a broken state, where every later request fails at once with the original exception. Create a new stub with getByName() or get() for each attempt.
How long can the old and new code versions run side by side?
For a normal deploy, typically seconds to minutes, according to the Durable Objects known issues page. With a gradual deployment, it lasts as long as your live deployment is configured to use more than one version. During that window a new Worker can call an object that still runs the old code.
Do WebSocket connections survive a deploy?
No. Cloudflare's WebSockets guide says code updates disconnect all WebSockets, because deploying a new version restarts every Durable Object. Clients have to reconnect. The Agents SDK clients such as useAgent and AgentClient reconnect automatically with exponential backoff.
Can a Durable Object reset when I haven't deployed anything?
Yes. Cloudflare lists Workers runtime updates, inactivity and decisions about where to host objects as other reasons an object shuts down. During a runtime update, in-flight requests have up to 30 seconds to complete. The known issues page also says enabling wrangler tail or dashboard logs requires a software update, which can replace the object.
What does “Durable Object storage operation exceeded timeout which caused object to be reset” mean?
Storage operations have a time limit so they can't block forever. In objects with a very large number of key-value pairs, deleteAll() can hit that limit and fail. Each deleteAll() call still makes progress, so Cloudflare says it is safe to retry until it succeeds.
Can I run cleanup code before the object shuts down?
No. Durable Objects don't provide shutdown hooks, because Cloudflare can't guarantee they would run in every case. Write state to storage as you go, so a new instance can pick up from the last saved point.
Sources
- Troubleshooting (Cloudflare Durable Objects docs)
- Lifecycle of a Durable Object (Cloudflare Durable Objects docs)
- Known issues (Cloudflare Durable Objects docs)
- Error handling (Cloudflare Durable Objects docs)
- Use WebSockets (Cloudflare Durable Objects docs)
- Gradual deployments with Durable Objects (Cloudflare Workers docs)
- Wrangler Workers commands (Cloudflare Workers docs)
- Client SDK (Cloudflare Agents docs)
- Polylane documentation
- Polylane full content
Boris Tane is the founder of Polylane. He previously founded Baselime, observability for the future of the cloud, which Cloudflare acquired. At Cloudflare he built and led the Workers observability team.
Related
- Cloudflare Durable Objects pending I/O keep-alive guide
From 2026-10-01, pending I/O keeps Cloudflare Durable Objects in memory after the client leaves. What counts, the 15-minute limit, flags and billing.
- How to Debug Cloudflare Workers Errors: Logs, Traces and Error Codes
Debug Cloudflare Workers errors step by step: read 1101 and 1102 codes, enable Workers Logs and source maps, use wrangler tail, DevTools and local traces.
- Fix Cloudflare “Error 1102: Worker exceeded resource limits”
Why a Cloudflare Worker returns Error 1102, how to tell a CPU time overrun from a 128 MB memory overrun, and the code and Wrangler changes that fix each.
- Cloudflare Hyperdrive connection errors: causes and fixes
Fix Cloudflare Hyperdrive connection errors: config codes 2008 to 2016, pool exhaustion, connection_refused and stale clients reused across Worker requests.
- Cloudflare Workers error 1101: causes and how to fix it
Error 1101 means your Cloudflare Worker threw an uncaught JavaScript exception. Find the exception in logs, match it to its cause, fix it and roll back fast.