 Boris Tane
Fix Cloudflare “Error 1102: Worker exceeded resource limits”
Explore with AI
Error 1102: Worker exceeded resource limitsError 1102 means your Worker went over its CPU time limit or its 128 MB memory limit, so Cloudflare stopped it and served an error page. Check Metrics > Errors > Invocation Statuses to see whether it was Exceeded CPU Time Limits or Exceeded Memory. Fix CPU overruns by profiling the hot code or raising limits.cpu_ms on the Paid plan, and fix memory overruns by streaming bodies and keeping large data out of the isolate.
On this page
- What “Worker exceeded resource limits” means
- Telling a CPU overrun from a memory overrun
- Cause 1: the Worker uses more CPU time than its plan allows
- Cause 2: one request buffers a large body into memory
- Cause 3: the isolate’s 128 MB fills up across requests
- Cause 4: startup work fails the deploy with error 10021
- Confirming the 1102s have stopped
- Keeping Workers under their CPU and memory limits
- Tracing a Worker’s 1102s back to the code with Polylane
- Common questions
Your users see a Cloudflare error page with code 1102 and the line Worker exceeded resource limits. The Worker didn’t throw. It ran out of room. The Workers runtime stopped it because it used more CPU time or more memory than its limits allow, and it had no response to send.
The message is the same for both limits, so the first job is to find out which one you hit. The Worker’s metrics tell you in one click. After that the fix is specific: profile and trim the code, or raise the CPU limit, for a CPU overrun; stream bodies and move large data out of the isolate for a memory overrun.
What “Worker exceeded resource limits” means
Cloudflare’s Error 1102 page defines it as a Worker that has exceeded its CPU time limit or its memory limit. The Workers limits page gives the numbers behind both:
- CPU time. 10 ms per HTTP request on the Workers Free plan. On the Workers Paid plan the default is 30 seconds, and you can raise it to 5 minutes. CPU time is the time spent executing your code, such as loops and JSON parsing. Waiting on
fetch(), KV reads or database queries does not count. - Memory. 128 MB per isolate on both plans, including the JavaScript heap and WebAssembly allocations. The limit applies to the isolate, and one isolate can handle many requests at the same time.
Each limit leaves its own trace. The client gets the same 1102 page either way, but the dashboard, analytics and Logpush name them differently:
- CPU:
Exceeded CPU Time Limitsunder Metrics > Errors > Invocation Statuses, outcomeexceededCpu. - Memory:
Exceeded Memoryin the same chart, outcomeexceededMemory. You may also see the runtime errorMemory limit would be exceeded before EOFwhen the Worker tries to buffer a body that would cross the limit.
The errors reference still describes 1102 in its table as a CPU time overrun, so don’t let that convince you memory is ruled out. The support page and the limits page both map memory overruns to 1102 too.
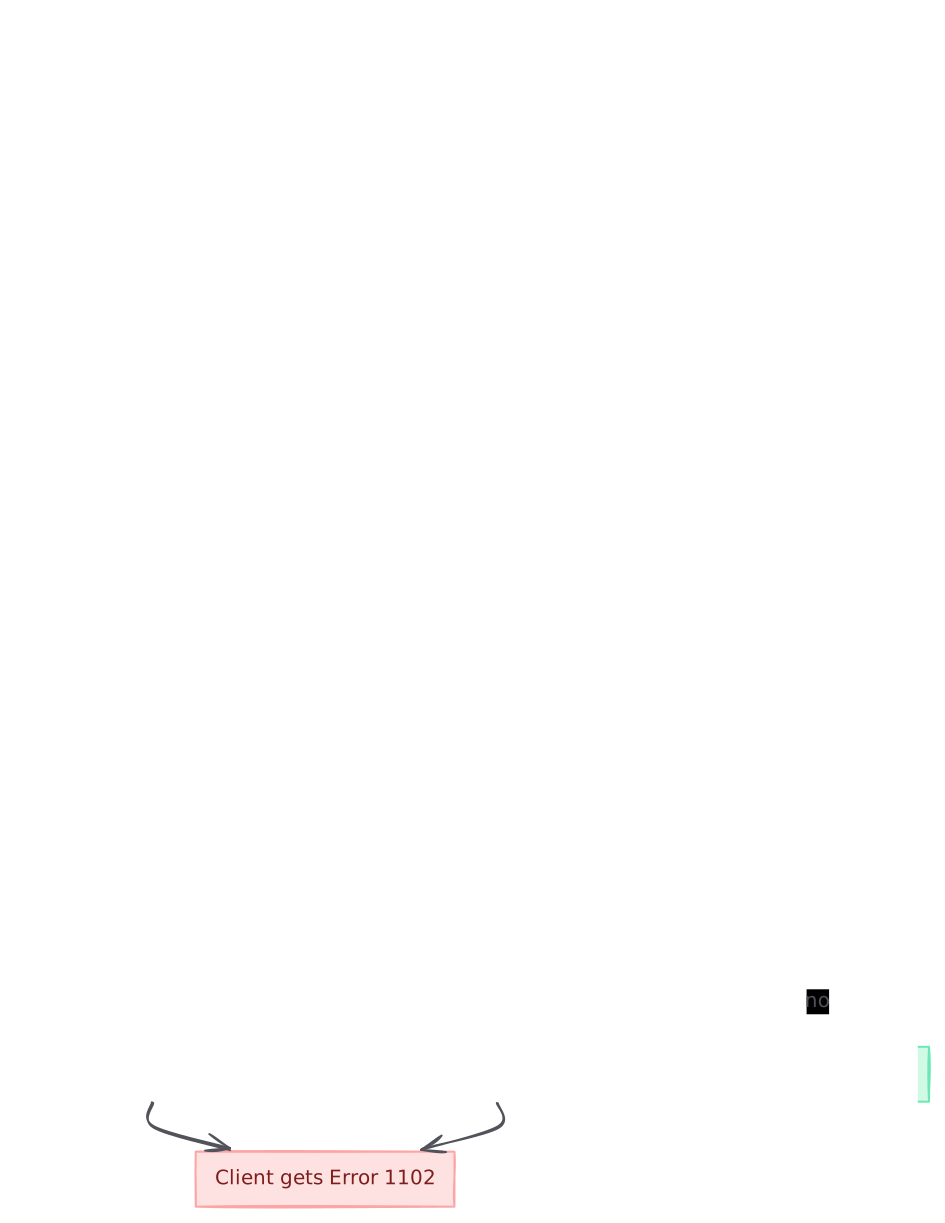
At Cloudflare I built and led the Workers observability team, and the invocation status was always the first thing to look at for a 1102. It splits the problem in two before you open any code.
Telling a CPU overrun from a memory overrun
Start in the dashboard:
- Go to Workers & Pages and select the Worker.
- Under Metrics, select Errors > Invocation Statuses.
- Read the two rows: Exceeded CPU Time Limits and Exceeded Memory. Note when they started and whether the start lines up with a deploy.
Then find the requests behind them in Workers Logs. Logs only exist if observability is on for the Worker. Check your Wrangler file:
{
  "observability": {
    "enabled": true,
    "head_sampling_rate": 1
  }
}[observability]
enabled = true
head_sampling_rate = 1head_sampling_rate defaults to 1, which logs every request. A low value can hide the few requests that blow the limit.
In the Workers Logs query builder, the errors reference suggests $metadata.error EXISTS to find every log with an error, and filtering on $workers.outcome to find requests by result. The limits page names the outcomes exceededCpu and exceededMemory for analytics and Logpush; it doesn’t say Workers Logs uses the same strings, so check the outcome values your logs actually show before you save the filter:
$workers.outcome = "exceededCpu"
$workers.outcome = "exceededMemory"
Each Worker invocation writes one invocation log, and CPU time and wall time appear in it. Group the failing requests by path. If one route or one kind of payload owns most of them, you have found where to look.
Cause 1: the Worker uses more CPU time than its plan allows
Start here. CPU time is the only one of the two limits that differs by plan, and 10 ms on the Free plan is easy to cross. The limits page says the average Worker uses about 2.2 ms of CPU per request, while heavier work such as authentication, server-side rendering or parsing large payloads typically takes 10 to 20 ms. A Free plan Worker doing any of those sits right at its limit.
How to tell it’s yours: the Exceeded CPU Time Limits row is the one climbing, the logs show exceededCpu, and the invocation logs for those requests show CPU time at or near your limit.
The limits page also notes that each isolate has some built-in flexibility for a Worker that only goes over now and then. Once it hits the limit consistently, the runtime enforces it. So a route that was fine at low traffic or with small payloads can start failing when either grows.
Find the expensive code with a CPU profile
Measuring CPU time inside a production Worker is hard, because Workers only advance timers on I/O. Cloudflare’s CPU profiling guide does it locally with DevTools:
- Start the Worker locally:
npx wrangler dev - Press
Din the terminal to open DevTools. - Select the Profiler tab and select Start.
- Send requests that look like production. Hit the same route, with payloads of the same size. Remote bindings let you use production-like data.
- Select Stop and read the chart. Each box is a function, and its width is the CPU time it used. Switch to Heavy (Bottom Up) to list functions by total cost.
A large share of garbage collection in that list is a hint that you are also allocating too much, which leads to cause 2.
Cut the work per request
The 1102 support page lists the usual fixes:
- Reduce the number of iterations in loops.
- Optimise JSON parsing. Parse only the payloads you need, and avoid parsing the same body twice.
- Cache computed values. A value that is the same for every request can be computed once per isolate.
- Break large operations into smaller chunks, spread across multiple requests.
The limits page adds one more: move expensive computation to a Durable Object, or process the data in smaller chunks across multiple requests.
Raise the CPU limit on the Paid plan
If the work really needs the CPU, raise the limit. This only applies on Workers Paid, where you can go from the 30 second default up to 5 minutes. On the Free plan the limit stays at 10 ms.
- Set
limits.cpu_msin your Wrangler file. Inwrangler.jsonc:
Or in{ "limits": { "cpu_ms": 300000 // default is 30000 (30 seconds) } }wrangler.toml:[limits] cpu_ms = 300_000 - Deploy:
npx wrangler deploy - Or change it in the dashboard: Workers & Pages > your Worker > Settings, then adjust the CPU time limit.
Pick a value with headroom over what your slowest real request uses. Cron Triggers have their own ceiling: 30 seconds for schedules more often than once an hour, and 15 minutes for hourly or less often.
Cause 2: one request buffers a large body into memory
The memory limit is 128 MB on every plan. The quickest way to cross it is to read a whole request or response body into a string, an ArrayBuffer or a parsed object. The 1102 page names this pattern first: buffering a body that could be large.
How to tell it’s yours: Exceeded Memory is the row climbing, the logs show exceededMemory, and you may see Memory limit would be exceeded before EOF as a runtime error. The failing requests carry large uploads or call an upstream that returns large responses. Search your code for await request.text(), await response.arrayBuffer() or await response.json() on anything that isn’t small.
Stream the body through a TransformStream
The fix is to process the body as it flows. This version holds the whole upstream response in memory:
export default {
  async fetch(request, env, ctx): Promise<Response> {
    const upstream = await fetch("https://example.com/export.ndjson");
    const text = await upstream.text(); // the whole body lands in the isolate
    return new Response(text, { headers: upstream.headers });
  },
} satisfies ExportedHandler<Env>;
This version passes it through a TransformStream, so only the chunk in flight is in memory:
export default {
  async fetch(request, env, ctx): Promise<Response> {
    const upstream = await fetch("https://example.com/export.ndjson");
    let bytes = 0;
    const { readable, writable } = new TransformStream<Uint8Array, Uint8Array>({
      transform(chunk, controller) {
        bytes += chunk.byteLength; // do per-chunk work here
        controller.enqueue(chunk);
      },
      flush() {
        console.log({ message: "export streamed", bytes });
      },
    });
    ctx.waitUntil(upstream.body!.pipeTo(writable));
    return new Response(readable, { headers: upstream.headers });
  },
} satisfies ExportedHandler<Env>;
Steps:
- Find each place you read a body with
.text(),.json()or.arrayBuffer(). - For bodies whose size you don’t control, move the work into a
TransformStream, or usenode:streamif your code is already written against Node streams. - When you call
fetch()and don’t need the response body, cancel it to free the memory, as the limits page shows:const response = await fetch(url); if (response.status > 299) { response.body?.cancel(); } - Be careful with code that grows a string or array on every chunk. The 1102 page warns against appending to strings or arrays repeatedly, and that undoes the streaming.
Cause 3: the isolate’s 128 MB fills up across requests
The limit is per isolate. The limits page is explicit that a single isolate handles many requests concurrently, and every one of them draws on the same 128 MB. So the request that fails is often a normal request that arrived while memory was already full.
How to tell it’s yours: exceededMemory shows up across many routes, including small ones. It gets worse with traffic, and requests that fail in production pass when you replay them one at a time. Look in your code for data held at module scope: a cache in a Map that never evicts, a large JSON file imported into the bundle, an array that grows on each request.
When an isolate crosses 128 MB, the runtime lets in-flight requests complete and creates a new isolate for the requests that follow. During extremely high load it may cancel some incoming requests to stay stable. A leak shows as a sawtooth: memory climbs, the isolate is replaced, and it climbs again.
Take a memory snapshot
The memory profiling guide uses the same DevTools session:
- Run
npx wrangler devand pressD. - Select the Memory tab.
- Send a large volume of requests, with
curlin a loop or a load tool. - Select Take snapshot, then choose Statistics to see which types hold the memory.
- Send more traffic and take a second snapshot. Whatever keeps growing between the two is your leak. The Summary view lists the objects, and clicking through takes you to the code that keeps them alive.
Keep large data out of the isolate
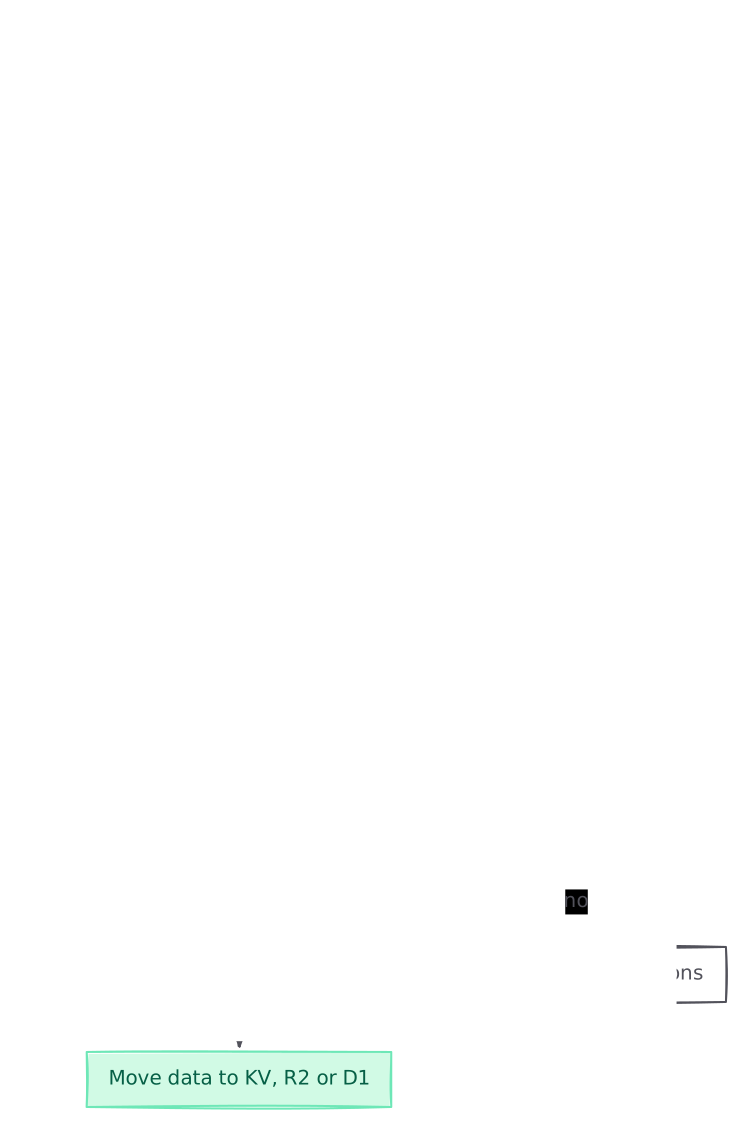
The limits page recommends storing large data in KV, R2 or D1 and keeping it out of Worker memory. Here a lookup table is bundled and parsed into every isolate:
import prices from "./prices.json"; // parsed into every isolate at startup

export default {
  async fetch(request, env, ctx): Promise<Response> {
    const sku = new URL(request.url).searchParams.get("sku") ?? "";
    return Response.json(prices[sku] ?? null);
  },
} satisfies ExportedHandler<Env>;
Store each entry under its own key in KV and read only the one you need:
export default {
  async fetch(request, env, ctx): Promise<Response> {
    const sku = new URL(request.url).searchParams.get("sku") ?? "";
    const price = await env.PRICES.get(`sku:${sku}`, "json");
    return Response.json(price);
  },
} satisfies ExportedHandler<Env>;
{
"kv_namespaces": [{ "binding": "PRICES", "id": "<namespace-id>" }]
}For an in-memory cache you want to keep, give it a hard size cap and evict old entries.
One dependency is worth checking. The limits page says that if your Worker uses Zod, you should use version 4.5.0 or later, because earlier versions use substantially more memory per schema:
npm ls zod
npm install zod@^4.5.0
We hit this ourselves in Durable Objects, where an isolate filled with schemas built at module load before it served a request. The write-up is in how we fixed our Durable Objects memory exceeded errors.
Cause 4: startup work fails the deploy with error 10021
A related error shows up when you deploy. A Worker must parse and run its global scope, everything outside the handlers, within 1 second. If it can’t, the upload fails validation with Script startup exceeded CPU time limit, error code 10021. The errors reference lists a memory twin as well: Script startup exceeded memory limit, for top-level code that allocates more than 128 MB.
How to tell it’s yours: wrangler deploy or wrangler versions upload fails with one of those messages. Users don’t see a 1102, because the new version never goes live. Heavy startup code also eats into the memory every request has left, which can feed cause 3.
Steps:
- Profile the startup phase locally:
It prints a summary and writes anpx wrangler check startup.cpuprofilefile you can open in Chrome DevTools or VS Code. When a deploy fails with a startup time error, Wrangler generates this profile for you. - Check the bundle size, since larger bundles start slower:
npx wrangler deploy --outdir bundled/ --dry-run - Move expensive setup out of global scope, into the handler or to build time. The limits page names generating or consuming a large schema at the top level as a common cause. Build it on first use:
let schemas: ReturnType<typeof buildSchemas> | undefined; function getSchemas() { schemas ??= buildSchemas(); return schemas; } export default { async fetch(request, env, ctx): Promise<Response> { const body = getSchemas().order.parse(await request.json()); return Response.json({ ok: true, id: body.id }); }, } satisfies ExportedHandler<Env>; - Deploy with
npx wrangler@latest deployand readstartup_time_msin the output.
Confirming the 1102s have stopped
- Deploy the fix and note the time.
- Watch Metrics > Errors > Invocation Statuses. The Exceeded CPU Time Limits or Exceeded Memory row should fall to zero from the deploy onward.
- In Workers Logs, run your outcome filter again for the period after the deploy. It should return nothing.
- For a CPU fix, open a few invocation logs on the route that used to fail and compare the CPU time with your limit. A fix that only brings CPU time down to just under the limit will fail again when payloads grow. You want comfortable headroom.
- For a memory fix, repeat the load test against
wrangler devwith two snapshots. The growth between them should be gone.
Keeping Workers under their CPU and memory limits
- Alert on the outcomes. Send Workers trace events to your log tool with Logpush and alert on
exceededCpuandexceededMemory. CPU time and wall time appear at the top level of the Workers Trace Events object. - Run
npx wrangler check startupin CI, so a dependency that makes startup heavier fails the build before it fails a deploy. - Stream by default. Treat
.text()and.arrayBuffer()on a body you don’t control as a review comment. - Cap every module-scope cache. A cache with no size limit grows until the isolate is replaced.
- Keep sampling high enough to catch the rare request. A
head_sampling_rateof 0.01 logs one request in a hundred, and the one that blew the limit may not be in it. - Set
cpu_mson purpose on the Paid plan, so the limit reflects the work the Worker does.
Tracing a Worker’s 1102s back to the code with Polylane
Polylane connects to your Cloudflare account with a read-only token and triages the account’s alerts automatically. A Worker that starts failing on resource limits becomes one issue, which an agent investigates using the logs and your code. When the cause is a code change, the fix arrives as a pull request for you to review.
Running on Cloudflare? See how Polylane monitors Cloudflare in production.
Common questions.
Is Error 1102 about CPU or memory?
It can be either. Cloudflare returns the same page and the same message, Worker exceeded resource limits, for both. Open the Worker in the dashboard and go to Metrics > Errors > Invocation Statuses: CPU overruns show as Exceeded CPU Time Limits and memory overruns as Exceeded Memory. In analytics and Logpush the outcomes are exceededCpu and exceededMemory.
What is the CPU time limit for a Cloudflare Worker?
On the Workers Free plan it is 10 ms per HTTP request. On the Workers Paid plan the default is 30 seconds, and you can raise it to 5 minutes (300,000 ms) with limits.cpu_ms in your Wrangler file or in the Worker's Settings in the dashboard. Cron Triggers on Paid get 30 seconds for intervals under an hour and 15 minutes for an hour or more.
Can I raise the 128 MB memory limit?
There is no Wrangler setting for it. The limits page lists 128 MB per isolate on both the Free and Paid plans, and it covers the JavaScript heap and WebAssembly allocations. Cloudflare's limits page links a Limit Increase Request Form for limits in general, and Cloudflare contacts you if the limit can be increased.
Does time spent waiting on fetch count toward CPU time?
No. CPU time only counts the time the CPU spends executing your code, such as loops and JSON parsing. Waiting on fetch() calls, KV reads or database queries does not count. A Worker that is slow because of a slow upstream will not hit 1102 for that reason.
Why does Error 1102 only happen on some requests?
Two reasons. Each isolate has some built-in flexibility for a Worker that only goes over the CPU limit now and then, and the limit is enforced once it happens consistently. Memory is shared by every request an isolate handles at once, so a request that is fine on its own can push the isolate over 128 MB when it lands next to a few heavy ones.
What is the difference between Error 1101 and Error 1102?
1101 means the Worker threw a JavaScript exception it never caught. 1102 means it went over a resource limit, CPU time or memory. The dashboard counts them separately: Uncaught Exception for 1101, and Exceeded CPU Time Limits or Exceeded Memory for 1102.
What does Script startup exceeded CPU time limit mean?
It is the deploy-time version of this problem. Cloudflare runs your Worker's global scope when you deploy, and if that takes more than the 1 second startup limit the deploy fails with validation error 10021. Run npx wrangler check startup to get a CPU profile of the startup phase, then move the expensive work into your handler or to build time.
Can Error 1102 show up as a 503?
Yes. Cloudflare's 1102 troubleshooting page lists Error 503 as related, because Workers CPU or memory limits can also cause it. If you see 503s on a Worker route, check the same Invocation Statuses chart before you look anywhere else.
Sources
- Error 1102 (Cloudflare Support docs)
- Limits (Cloudflare Workers docs)
- Errors and exceptions (Cloudflare Workers docs)
- Profiling CPU usage (Cloudflare Workers docs)
- Profiling Memory (Cloudflare Workers docs)
- Workers Logs (Cloudflare Workers docs)
- Wrangler Workers commands (Cloudflare Workers docs)
- Polylane documentation
- Polylane full content
Boris Tane is the founder of Polylane. He previously founded Baselime, observability for the future of the cloud, which Cloudflare acquired. At Cloudflare he built and led the Workers observability team.
Related
- Cloudflare Workers error 1101: causes and how to fix it
Error 1101 means your Cloudflare Worker threw an uncaught JavaScript exception. Find the exception in logs, match it to its cause, fix it and roll back fast.
- How to Debug Cloudflare Workers Errors: Logs, Traces and Error Codes
Debug Cloudflare Workers errors step by step: read 1101 and 1102 codes, enable Workers Logs and source maps, use wrangler tail, DevTools and local traces.
- Fix “Durable Object reset because its code was updated”
Why a deploy makes Cloudflare Durable Objects throw “reset because its code was updated”, and how to retry safely, keep clients connected and lose no state.
- Cloudflare Hyperdrive connection errors: causes and fixes
Fix Cloudflare Hyperdrive connection errors: config codes 2008 to 2016, pool exhaustion, connection_refused and stale clients reused across Worker requests.
- Workers Issues: route Cloudflare errors to coding agents
Cloudflare's new Workers Issues groups exceptions and 5xx errors and sends them to Claude Code, Cursor, Devin or a webhook. Setup, automations and limits.