 Boris Tane
Fix “remaining connection slots are reserved” in PostgreSQL
Explore with AI
FATAL: remaining connection slots are reserved for non-replication superuser connectionsPostgres has used up every connection slot except the few it keeps back for superusers, so it refuses new logins from ordinary roles with SQLSTATE 53300. Find which app and role hold the connections in pg_stat_activity, close the idle ones, then put a pooler such as Supabase's transaction mode on port 6543 or PgBouncer in front of the database and cap each client's pool. Raise max_connections or the compute size only once the connection count is under control.
On this page
- What “remaining connection slots are reserved” means
- Why the slots ran out: who holds the connections
- Serverless functions connecting straight to Postgres
- Idle and leaked connections
- Pool size multiplied by replicas and services
- max_connections set too low for the workload
- Confirming the database has headroom again
- Stopping the slots filling up again
- Tracing a full Supabase connection pool with Polylane
- Common questions
This error usually arrives in a burst. A deploy goes out, traffic rises, or a batch of serverless functions wakes up, and suddenly every new request fails at login with FATAL: remaining connection slots are reserved for non-replication superuser connections. Requests that already hold a connection keep working. Anything that needs a new one gets turned away.
Postgres is telling you it is nearly full. It still has a handful of connection slots, but it keeps those for superusers so an administrator can always get in to fix things. Your app’s role isn’t a superuser, so it gets refused. The fix is to find who is holding the other slots, release the ones nobody is using, and stop your clients from asking for more than the database has.
What “remaining connection slots are reserved” means
Every client connection to Postgres takes one slot out of a fixed pool sized by max_connections. The PostgreSQL docs say the default is typically 100, and the setting can only be changed at server start. A second setting, superuser_reserved_connections, keeps some of those slots back. Its default is 3. Once the number of active connections reaches max_connections minus superuser_reserved_connections, only superusers can connect.
The check lives in InitPostgres() in src/backend/utils/init/postinit.c. On PostgreSQL 15 and earlier, a regular backend for a role that isn’t a superuser asks whether there are still ReservedBackends free slots. If not, it raises FATAL with SQLSTATE 53300, which errcodes.txt names too_many_connections.
PostgreSQL 16 split the reserve in two. The release notes add a reserved_connections setting for roles with the pg_use_reserved_connections role, and the REL_16_STABLE source rewords the message. You now see one of these, still with SQLSTATE 53300:
FATAL:  remaining connection slots are reserved for roles with the SUPERUSER attribute
FATAL:  remaining connection slots are reserved for roles with privileges of the "pg_use_reserved_connections" role
The first appears when fewer free slots remain than superuser_reserved_connections. The second appears when the free slots sit inside the reserved_connections band and your role lacks pg_use_reserved_connections. reserved_connections defaults to 0, so on most PostgreSQL 16 and later servers you only ever see the SUPERUSER wording.
When the last slot goes too, everyone gets sorry, too many clients already, from the same SQLSTATE. So the ceiling for your app’s roles is:
usable slots = max_connections - superuser_reserved_connections - reserved_connectionsOn a default server that is 100 - 3 - 0 = 97.
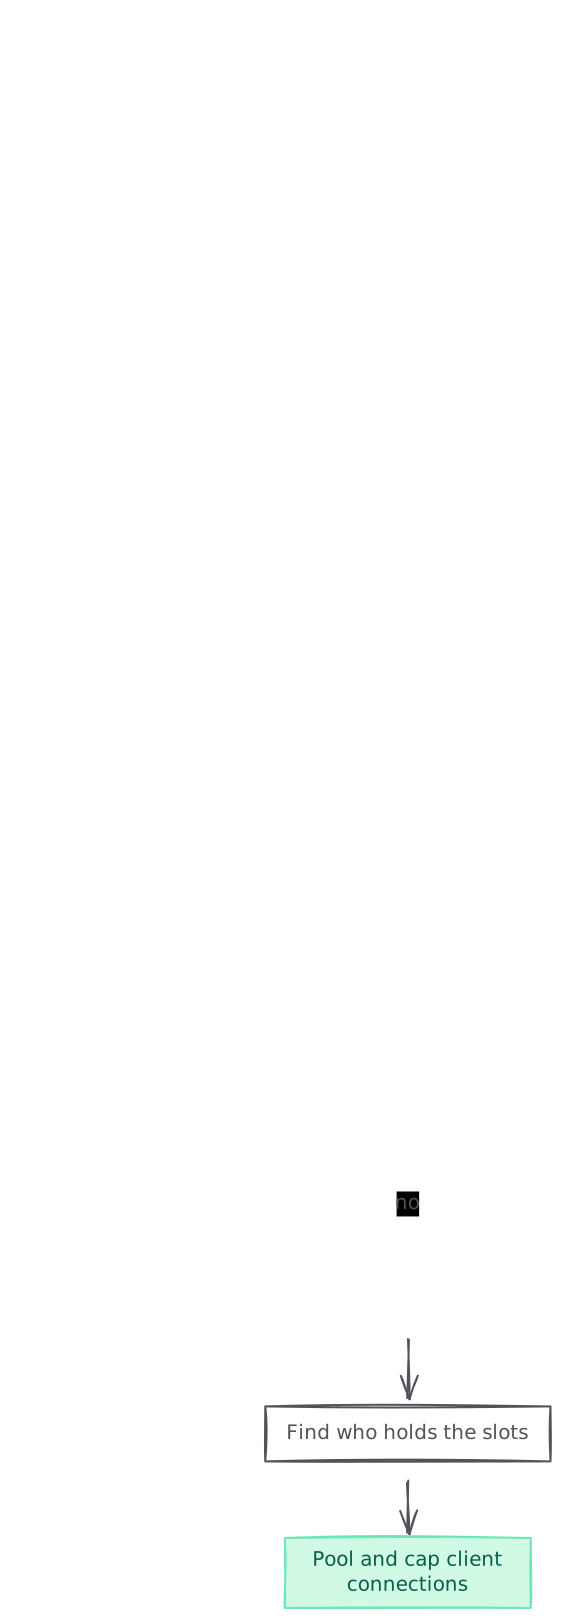
Why the slots ran out: who holds the connections
Before you change anything, connect as a superuser (the reserve exists for exactly this) and count the connections by role, application and state. pg_stat_activity has one row per server process. The statistics docs say backend_type is client backend for ordinary client sessions, and state is one of active, idle, idle in transaction, idle in transaction (aborted), fastpath function call or disabled.
SELECT usename,
       application_name,
       client_addr,
       state,
       count(*)                              AS connections,
       max(now() - state_change)             AS longest_in_state
FROM pg_stat_activity
WHERE backend_type = 'client backend'
GROUP BY usename, application_name, client_addr, state
ORDER BY connections DESC;
Then compare the total with the limit:
SELECT current_setting('max_connections')::int                AS max_connections,
       current_setting('superuser_reserved_connections')::int AS superuser_reserved,
       current_setting('reserved_connections')::int           AS reserved,  -- PostgreSQL 16+
       (SELECT count(*) FROM pg_stat_activity
        WHERE backend_type = 'client backend')                AS client_connections;
On PostgreSQL 15 and earlier, drop the reserved_connections line, because the setting doesn’t exist there.
On Supabase, the role tells you which service owns a connection. The connection management guide maps them: authenticator is the Data API (PostgREST), supabase_auth_admin is Auth, supabase_storage_admin is Storage, supabase_admin is Supabase monitoring and Realtime, and postgres or your own roles are the Dashboard and external tools such as Prisma, SQLAlchemy and psql.
The result usually points at one of four causes.
Serverless functions connecting straight to Postgres
How to tell it’s yours: a large count for one role, many distinct client_addr values, short connection lifetimes, and the error lines up with traffic spikes or a burst of function invocations.
Each function instance opens its own connection, or its own pool, and many instances run at once. Supabase’s connection guide recommends the shared pooler in transaction mode for serverless and edge functions, because they open many short-lived connections. Transaction mode hands a server connection to a client only for the length of a transaction, so many clients share a few Postgres slots.
Fix: send serverless traffic through a transaction-mode pooler.
- Copy the transaction pooler string from the Supabase Dashboard. It uses port 6543 and a pooler host you can’t build from the region alone:
postgresql://postgres.[PROJECT-REF]:[YOUR-PASSWORD]@[POOLER-HOST]:6543/postgres - Create the client once at module scope, outside the request handler, so warm invocations reuse it.
- Set the pool to 1 connection per function instance.
- Turn off prepared statements, which transaction mode doesn’t support. Supabase lists
prepare: falsefor Postgres.js and Drizzle,pgbouncer=truefor Prisma,statement_cache_size=0for asyncpg andprepareThreshold=0for JDBC. - Set SSL to
require.
For Postgres.js, that looks like:
import postgres from "postgres";

// Module scope: one client per function instance.
const sql = postgres(process.env.DATABASE_URL!, {
  max: 1,
  prepare: false,
  ssl: "require",
});

export default async function handler() {
  const rows = await sql`select now()`;
  return Response.json(rows);
}
Keep migrations off the transaction pooler. Supabase says to run them over the direct connection, because they are single sessions using native Postgres commands.
Outside Supabase, PgBouncer does the same job. Its configuration reference defaults pool_mode to session, which only returns a server connection to the pool after the client disconnects. Set it to transaction for serverless clients:
[databases]
app = host=10.0.0.5 port=5432 dbname=app

[pgbouncer]
pool_mode = transaction
max_client_conn = 1000
default_pool_size = 20
default_pool_size (default 20) is the most server connections PgBouncer opens per user and database pair. max_client_conn (default 100) is how many clients it accepts. Keep the sum of server-side pools below your usable slots.
Idle and leaked connections
How to tell it’s yours: most rows have state = 'idle' or 'idle in transaction', and longest_in_state runs to minutes or hours. Often one application_name dominates.
An idle session is waiting for its next command. An app that opens connections and never closes them, or a pool with no idle timeout, fills the slots this way. idle in transaction is worse. The client defaults docs say an open transaction also stops vacuum from removing recently dead rows, which leads to table bloat.
Fix: release them now, then stop them building up.
- List the worst offenders:
SELECT pid, usename, application_name, state, now() - state_change AS for_how_long FROM pg_stat_activity WHERE backend_type = 'client backend' AND state IN ('idle', 'idle in transaction') ORDER BY state_change LIMIT 50; - End the idle sessions of the app that leaks.
pg_terminate_backendsends SIGTERM to the backend. The admin functions docs say you need to be a member of the target’s role or havepg_signal_backend, and only superusers can end superuser sessions:SELECT pg_terminate_backend(pid) FROM pg_stat_activity WHERE backend_type = 'client backend' AND state = 'idle' AND application_name = 'my-api' AND state_change < now() - interval '10 minutes'; - Set
idle_in_transaction_session_timeoutfor the app’s role. It ends any session that stays idle inside an open transaction for longer than the value, and its default of 0 disables it:
New sessions for that role pick up the setting. Existing ones keep the old value until they reconnect.ALTER ROLE app_user SET idle_in_transaction_session_timeout = '60s'; - Fix the leak in code. Release every connection in a
finallyblock, or use the pool’s query helper, which checks a connection out and back in for you.
idle_session_timeout also exists, for sessions idle outside a transaction. The Postgres docs warn against using it on connections that come through a pooler or other middleware, which may not react well when the server closes a connection without warning. Apply it per role for interactive users, if at all.
Pool size multiplied by replicas and services
How to tell it’s yours: the count per client_addr is steady and equals your pool size, and the total grew when you scaled out, added a worker, or deployed a new service on the same database.
Every app instance keeps its own pool. The total is pool size times instances, summed across every service. The Prisma connection pool docs give two defaults worth knowing. Prisma ORM 6 used num_cpus::get_physical() * 2 + 1 connections per instance. The Prisma 7 pg driver adapter uses max: 10. Ten replicas on Prisma 7 can ask for 100 connections before anything else connects.
Fix: budget the slots and cap each pool.
- Write down every client: app replicas, workers, cron jobs, migrations, BI tools and admin sessions.
- Divide the usable slots between them, with headroom. On Supabase, the guide says to stay under 40% of the database’s max connections for the pooler if you use the Data API heavily, and up to 80% otherwise, to leave room for Auth and other services.
- Set each pool’s maximum explicitly. With the Prisma 7
pgadapter:import { PrismaPg } from "@prisma/adapter-pg"; import { PrismaClient } from "./generated/prisma/client"; const adapter = new PrismaPg({ connectionString: process.env.DATABASE_URL, max: 5, idleTimeoutMillis: 10_000, }); export const prisma = new PrismaClient({ adapter }); - Recheck the budget whenever autoscaling limits change. The number that matters is the maximum replica count.
max_connections set too low for the workload
How to tell it’s yours: the connections are all legitimate and mostly active, pools are already capped, a pooler is already in place, and you still hit the limit at peak.
On Supabase, max_connections follows the compute size. The compute docs list 60 for Nano and Micro, 90 for Small, 120 for Medium, 160 for Large and 240 for XL, rising to 500 on the largest sizes. The Supabase troubleshooting entry for this error says that if you already pool and still hit the limit, upgrade the compute add-on.
Fix: raise the ceiling, knowing what it costs.
- On Supabase, upgrade the compute size in the Dashboard, or set the value directly with the CLI. The config guide marks
max_connectionsas CLI only, and changing it restarts the database:supabase postgres-config update --project-ref <project-ref> --experimental \ --config max_connections=200 - On self-managed Postgres, edit
postgresql.confand restart:max_connections = 200 superuser_reserved_connections = 3 - On a standby, set
max_connectionsto the same value or higher than on the primary. The Postgres docs say queries aren’t allowed on the standby otherwise.
PostgreSQL sizes some resources, including shared memory, directly from max_connections. A bigger limit costs memory on every server, so treat it as the last lever.
Confirming the database has headroom again
Run the count query again during normal traffic and at peak. The fix holds when:
SELECT count(*) AS client_connections,
       current_setting('max_connections')::int
         - current_setting('superuser_reserved_connections')::int
         - current_setting('reserved_connections')::int AS usable_slots
FROM pg_stat_activity
WHERE backend_type = 'client backend';
client_connections stays clearly below usable_slots, and your logs show no new FATAL lines with SQLSTATE 53300. Redeploy or scale out once on purpose and watch the count. It should rise by your per-instance pool size and no more.
Stopping the slots filling up again
- Alert on connection pressure. Alert well before client connections reach the usable slots. Supabase’s Grafana dashboard has a Client Connections graph for both Supavisor and Postgres, and the Dashboard’s Database client connections chart (Teams and Enterprise) breaks them down by Postgres, PostgREST, Reserved, Auth, Storage and other roles.
- Alert on the log line. Match
remaining connection slots are reservedandtoo many clientsin your Postgres logs. Either one means users are already seeing errors. - Cap every pool in code. Never rely on a driver’s default, which differs between libraries and versions.
- Put a budget in the deploy checklist. Max replicas times pool size, summed across services, must fit inside the usable slots.
- Keep the idle-in-transaction timeout on for application roles.
- Leave the superuser reserve alone. It is what lets you log in and run the queries above during an incident.
Tracing a full Supabase connection pool with Polylane
Polylane connects a Supabase organisation, syncs each project’s database with logs and checks on it, and links the auth, storage, realtime and REST services to the Postgres database they sit in front of. It also triages the account’s alerts. When a confirmed cause is a code defect, such as a pool with no cap, the fix arrives as a pull request for you to review.
Running on Supabase? See how Polylane monitors Supabase in production.
Common questions.
Why does PostgreSQL 16 show a different message for the same problem?
PostgreSQL 16 added the reserved_connections setting and the pg_use_reserved_connections role, and reworded the check. When fewer free slots remain than superuser_reserved_connections, it prints “remaining connection slots are reserved for roles with the SUPERUSER attribute”. When the free slots fall inside the reserved_connections band and your role lacks pg_use_reserved_connections, it prints “reserved for roles with privileges of the pg_use_reserved_connections role”. Both carry SQLSTATE 53300.
What is the difference between this error and “sorry, too many clients already”?
Both use SQLSTATE 53300 (too_many_connections). “remaining connection slots are reserved” means a few slots are still free but held back for superusers or reserved roles. “sorry, too many clients already” means no slot is left at all, so even a superuser can't log in. Same cause, one step further along.
How many connections can a non-superuser actually open?
max_connections minus superuser_reserved_connections minus reserved_connections. With the defaults of 100, 3 and 0, that is 97. On Supabase, max_connections follows the compute size, for example 60 on Nano and Micro, 90 on Small and 120 on Medium.
Should I raise max_connections to fix it?
Only after you have found where the connections come from. PostgreSQL sizes some resources, including shared memory, directly from max_connections, and it can only be changed at server start. On Supabase it is set with supabase postgres-config update --config max_connections=200 and needs a restart, so a leak will fill the bigger limit too.
Which Supabase connection string should a serverless function use?
The shared pooler in transaction mode, on port 6543. Supabase recommends creating the client once at module scope, setting the pool to 1 connection, turning off prepared statements and setting SSL to require. With Prisma, add pgbouncer=true to that URL.
Is it safe to terminate idle connections with pg_terminate_backend?
Terminating a session in the idle state drops a connection that is waiting for its next command, so the client sees a closed connection and its pool should open a new one. Avoid ending sessions that are active or idle in transaction unless you accept that their open transaction is rolled back. You need superuser or pg_signal_backend to end another role's session.
What pool size should I give each app instance?
Work back from the limit. Divide the non-superuser slots by the number of instances that can run at once, then leave room for migrations and admin tools. Prisma ORM 6 defaulted to num_physical_cpus * 2 + 1 per instance and the Prisma 7 pg adapter defaults to 10, so ten instances can ask for 100 connections.
Sources
- postinit.c, REL_15_STABLE (PostgreSQL source)
- postinit.c, REL_16_STABLE (PostgreSQL source)
- errcodes.txt (PostgreSQL source)
- Connections and Authentication (PostgreSQL docs)
- Client Connection Defaults (PostgreSQL docs)
- System Administration Functions (PostgreSQL docs)
- The Cumulative Statistics System (PostgreSQL docs)
- PostgreSQL 16 release notes
- Database error: remaining connection slots are reserved (Supabase Docs)
- Connect to your database (Supabase Docs)
- Connection management (Supabase Docs)
- Compute and Disk (Supabase Docs)
- Customizing Postgres configs (Supabase Docs)
- ALTER ROLE (PostgreSQL docs)
- PgBouncer configuration
- Connection pool (Prisma ORM v7 docs)
- Polylane documentation
- Polylane full content
Boris Tane is the founder of Polylane. He previously founded Baselime, observability for the future of the cloud, which Cloudflare acquired. At Cloudflare he built and led the Workers observability team.
Related
- How to Monitor a Supabase App in Production
Monitor a Supabase app in production: scrape the Metrics API into Prometheus, drain logs, run SQL health checks, trace requests and alert on what matters.
- Cloudflare Hyperdrive connection errors: causes and fixes
Fix Cloudflare Hyperdrive connection errors: config codes 2008 to 2016, pool exhaustion, connection_refused and stale clients reused across Worker requests.
- Fix Prisma “P1001: Can't reach database server”
Why Prisma prints “P1001: Can't reach database server”, how to test the host and port it names, and how to fix private hosts, IPv6, paused databases and URLs.
- How to monitor a vibe-coded app in production
Monitor a vibe-coded app in production: surface swallowed errors, add a health route, tag deploys, watch cron jobs and alert on what users feel first.
- Fix “Durable Object reset because its code was updated”
Why a deploy makes Cloudflare Durable Objects throw “reset because its code was updated”, and how to retry safely, keep clients connected and lose no state.