Boris Tane
Turn your app into a context graph
Explore with AI
We’re getting closer to self-improving software, where agents continuously read the signals your app produces and improve it automatically. To do that, an agent first has to understand how your app fits together. It needs to know which services talk to which databases, what each queue triggers, and which repository deploys what.
So, before an agent reads a single log line, it’s necessary to give it a graph of everything your app uses to run: clouds, repos, observability providers, etc.
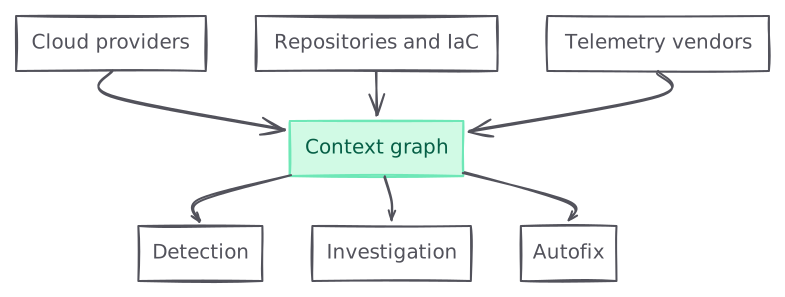
This is the context graph. Every resource in every connected account is a node, every relationship between them is an edge, and the graph is continuously updated, as you deploy new things, delete old ones, and refactor your codebase. The context graph also encompasses all the data that lives alongside the nodes, in vector databases, in key-value stores, etc. This additional data is the difference between an agent that can traverse a graph and one that actually understands your app.
This post walks through how we turn an app into a context graph: what goes into it, how we keep it in sync with every provider, and how we connect resources across clouds without guessing.
What’s in the context graph?
The context graph is made of nodes and edges. A node is a resource: a Lambda function, a Worker, a Kubernetes deployment, a repository, a team. An edge is a typed relationship between two of them, read in one direction: a queue triggers a function, a function assumes a role and connects_to a table, a repository deploys_to the function, a team owns the repository.
We use Cloudflare Durable Objects for the graph itself. Each workspace on Polylane gets its own instance, with both compute and SQLite storage, so there’s no cluster to run, no connection pool to manage, and no shared tables to keep tenants apart. The graph only holds what a resource is and how it connects to other nodes.
The majority of workspaces in Polylane have fewer than 100 nodes, but a subset of customers have more than 10,000 nodes. Our solution must scale to those apps too.
The graph itself is two tables, nodes and edges. A node’s identity is five fields, provider, account, region, type and id, and the database derives the key from them itself, so no caller can ever build it differently:
CREATE TABLE nodes (
    provider TEXT NOT NULL,
    account TEXT NOT NULL,
    region TEXT NOT NULL,
    type TEXT NOT NULL,
    id TEXT NOT NULL,
    composite_id TEXT GENERATED ALWAYS AS ('provider#' || provider || '#account#' || account || '#region#' || region || '#type#' || type || '#id#' || id) VIRTUAL NOT NULL UNIQUE,
    data TEXT,
    created INTEGER NOT NULL,
    updated INTEGER NOT NULL,
    -- ...
);
The data field holds the properties of the node, as JSON. For a Lambda function that’s all the data returned by the AWS API when calling GetFunction. Environment variable values are stripped before anything is stored, only the keys are kept:
{
  "FunctionName": "checkout-api",
  "Runtime": "nodejs22.x",
  "Handler": "dist/index.handler",
  "MemorySize": 1024,
  "Timeout": 30,
  "Architectures": ["arm64"],
  "Role": "arn:aws:iam::123456789012:role/checkout-api-role",
  "VpcConfig": { "SubnetIds": ["subnet-0a1b2c3d"], "SecurityGroupIds": ["sg-0e4f5a6b"] },
  "EventSourceMappings": [{ "EventSourceArn": "arn:aws:sqs:eu-west-1:123456789012:orders-events", "BatchSize": 10, "State": "Enabled" }],
  "LastModified": "2026-10-04T18:22:41.000+0000",
  "RevisionId": "4c1e9a0b-7d2f-4e61-9a3c-2b8d5f0e1a77",
  "State": "Active",
  "envVarCount": 3,
  "envVarKeys": ["ORDERS_TABLE", "STRIPE_SECRET_KEY", "LOG_LEVEL"],
  "packageType": "Zip",
  "imageUri": null
}
Edges point from one node’s key to another’s, and a pair of nodes can have at most one edge of each relationship:
CREATE TABLE edges (
    source TEXT,          -- composite_id of the node the edge starts from
    target TEXT,          -- composite_id of the node it points to
    relationship TEXT,    -- connects_to, triggers, deploys_to, owns, ...
    properties TEXT,      -- JSON: the evidence the edge was drawn from
    discovered_via TEXT,  -- infrastructure_sweep, environment_variables, repository, ...
    created_by TEXT NOT NULL,
    last_edited_by TEXT NOT NULL,
    created INTEGER NOT NULL,
    updated INTEGER NOT NULL,
    UNIQUE(source, target, relationship)
);
discovered_via records how we know the relationship between the nodes. It could be through an environment variable, an integration, or manually added by a user. The properties field keeps the evidence of the connection, like the DNS record an edge was drawn from, or the image reference and what it was matched on, so an agent can check why two resources are connected.
What lives next to the graph
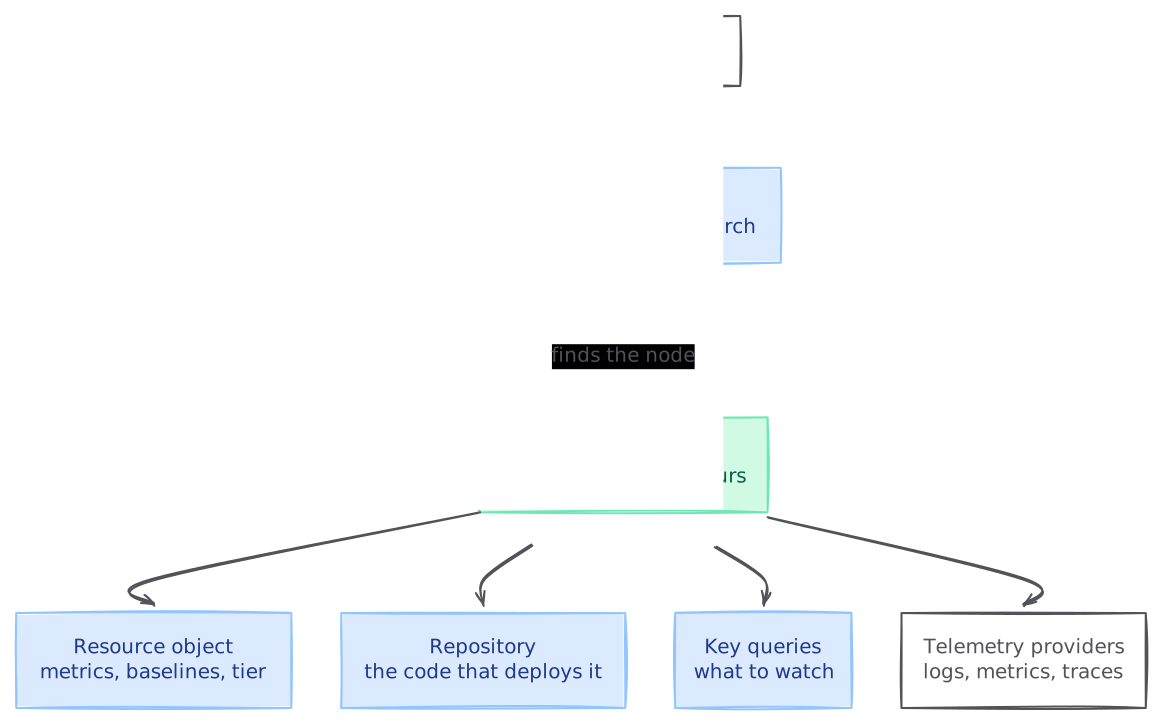
The context graph is not just the graph database. We also enrich each node with a wide range of additional data that the agent can access alongside it:
- A catalog that finds a resource from the name an engineer would use for it
- A resource object that remembers how each resource normally behaves, so the agent can tell healthy from broken without querying a provider
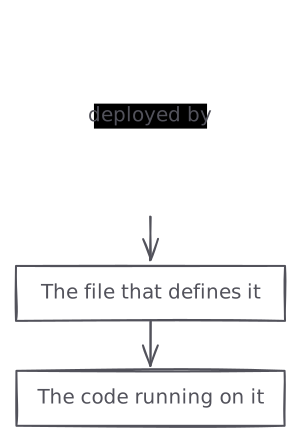
- The repository that deploys each resource, so the agent goes straight to the code that’s running on it
- Key queries, the questions worth asking about each resource when something goes wrong, prepared ahead of time
The catalog: finding the node
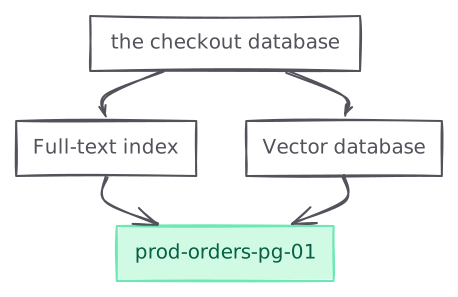
An agent rarely knows a node’s ID. It knows “the checkout database”. In order to use the graph and figure out its dependencies, it’s necessary to go from “the checkout database” to its ID in the cloud provider. We implemented a second Durable Object per workspace which holds a full-text search index over every node’s name and alternate names, alongside embeddings in a vector database. The agent can use this to find the ID of the database based on its human-readable name.
The resource object: is it healthy?
For the workspace with thousands of cloud resources, the agent should not need to call the observability provider to know basic metrics about the resource every time it’s accessing it, it’s actually impossible given all providers have pretty stringent rate-limits.
For every resource we keep its baseline of metrics, alongside recent timeseries and common logs. This data lets an agent quickly and cheaply know if a resource is healthy or misbehaving:
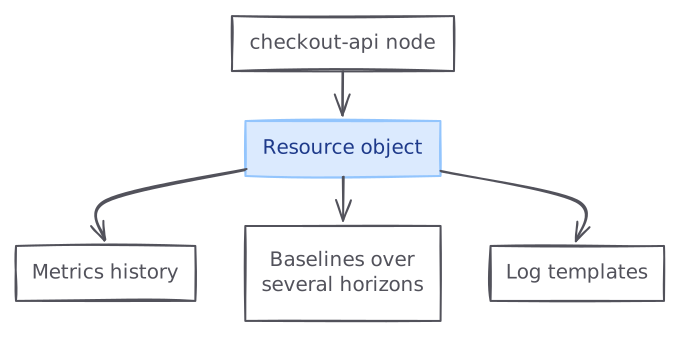
The baselines cover several horizons, so a Monday morning peak doesn’t read as an issue.
The repository: what’s running on it
An organisation can have hundreds of repositories, and an agent that has to guess which one is behind a failing service wastes its time in the wrong code. Every resource in the graph knows the repository that deploys it, and often the exact file that defines it: the Terraform module, the wrangler.toml, the task definition. When the agent needs to read code, it starts in the right place.
Key queries: what to watch
To further improve the context we give to the agents, for each node, we compute “key queries”. Key queries are the questions an engineer would ask about every piece of their architecture when they get paged. For example, for an auth service, they will want to know:
- How many logins are failing right now, and for what reason?
- How long does token verification take at the 95th percentile?
- Is the identity provider rate limiting us?
We compute these ahead of time by looking at metrics, logs but also custom spans a developer added to their codebase, such that we can answer the type of questions impossible to answer with just metrics.
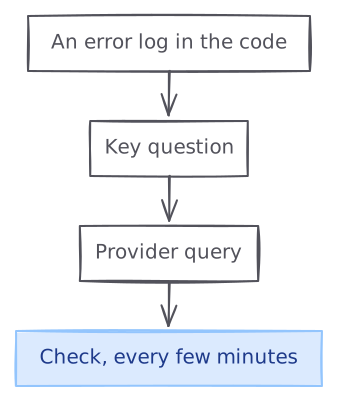
The graph is the index that joins all of this together. An agent investigating checkout-api starts from its node, walks to the database it connects to, checks that database’s baselines in its resource object, searches the repository that deploys it, and queries its logs, without ever being told where any of it lives.
How we keep the graph up to date
An app continuously evolves, and keeping the context graph in sync with the reality of the app is a complex challenge. We need to react to changes in the application and surgically create, update and delete nodes as they evolve in the application. Each cloud provider is different with different APIs and mechanisms, so we have to adapt to each:
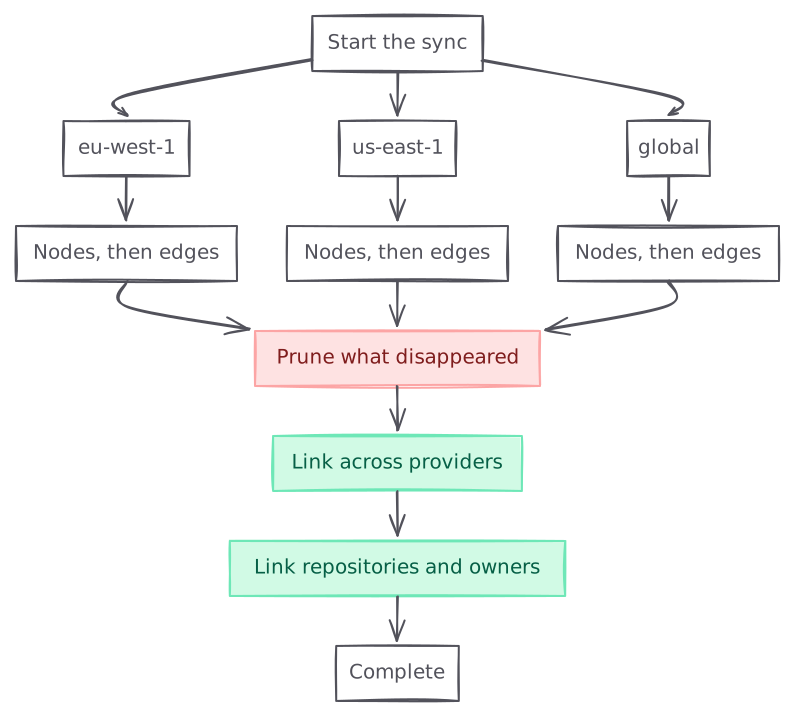
For example, for AWS we use CloudTrail, for Kubernetes we use a small Helm agent that dials out through a Cloudflare Tunnel, for Vercel we use webhooks, and for Cloudflare, we rely on audit logs.

 AWS 29%
 Kubernetes 28%
 Cloudflare 17%
 GitHub repositories 9.2%
 Railway 7.8%
 Vercel 3.7%
 Fly.io 1.7%
 Container registries 1.3%
 Convex 0.9%
 Trigger.dev 0.7%
 Supabase 0.4%
 PlanetScale 0.1%
 Render <0.1%
 Modal <0.1%
 ClickHouse Cloud <0.1%
The key constraints of syncing are how long it takes and how much of the provider’s rate limit budget it consumes. Every call a sync makes is a call the customer’s own tooling can’t, so a sync has to finish quickly and touch as little as possible. Most of them find nothing to change: a PlanetScale or Supabase sync almost never adds or removes a resource, while an AWS sync touches about 20 resources and a Kubernetes one about 12. The chart below shows how long syncs take for each provider, from the fastest tenth to the slowest, and how much each one changes.
Connecting resources across clouds
Most applications run across multiple providers, for instance AWS for long-running containers, Cloudflare for CDN and edge-computing and Vercel for sandboxes. Syncing each cloud individually is great, but the interesting edges cross providers, because each provider only knows its own half.
After the provider work, every sync runs one shared linker over the whole workspace. A DNS record pointing at .elb.amazonaws.com connects to that load balancer, one pointing at .vercel.app to that Vercel project, .cfargotunnel.com to that tunnel. An environment variable holding an RDS endpoint connects the function to the database.
Put together, the syncs and the linkers give every customer a graph that looks like their stack rather than like any one provider’s console.
How agents use the graph
The Polylane agents get a narrow tools over the graph:
- find nodes by any field in the provider’s JSON
- read a node and its neighbours
- walk the graph in either direction, and
- compute a blast radius.
Agents really like findNodes as they use it to filter nodes across any dimensions. For example they can find all the AWS Lambda function with Go runtime in a single call.
| Tool | Share of calls | Median | p95 |
|---|---|---|---|
findNodes | 67% | 128 ms | 533 ms |
getNode | 21% | 519 ms | 1,494 ms |
getNodeEdges | 7.0% | 115 ms | 878 ms |
getInfraStats | 3.0% | 98 ms | 328 ms |
findNeighbours | 1.5% | 136 ms | 549 ms |
getBlastRadius | 0.3% | 118 ms | 314 ms |
traverseNodes | <0.1% | 85 ms | 259 ms |
The blast radius tool is used when the agent wants to know the downstream services of a specific node. It’s useful when it identifies a node as the potential cause of an incident and it wants to know grade the severity of the incident. For example, if a database fails, the services that connects_to it fail too, so the fault travels against the edge. If a queue fails, the functions it triggers stop, so the fault travels with it.
Agents are only as good as the context you give them. We built a system to create a rich context graph for any application, and it powers everything Polylane does.
Running on AWS? See how Polylane monitors AWS in production.
Related
- Amazon Bedrock Managed Agents (OpenAI preview): setup and limits
Amazon Bedrock Managed Agents, powered by OpenAI, entered preview on 29 Sep 2026. What it is, how to run a first session, and the preview limits to plan for.
- Cloudflare Containers agent sandboxes: startup and setup
Cloudflare Containers now start agent sandboxes in a median 648 ms. Set up the durable_object policy, runtime images and snapshots, and know the limits.
- How to attach Vercel Sandbox to a Secure Compute network
Vercel Sandbox now supports Secure Compute. Attach a sandbox to your network for static egress IPs and VPC peering, with steps, costs and gotchas.
- Cloudflare Durable Objects pending I/O keep-alive guide
From 2026-10-01, pending I/O keeps Cloudflare Durable Objects in memory after the client leaves. What counts, the 15-minute limit, flags and billing.
- Cloudflare K2: how to adopt serverless event streams
Cloudflare K2, announced 1 October 2026, is a serverless event stream on R2. What it is, how it differs from Queues, setup steps and beta limits.