

How we prevent slop from hitting prod
Explore with AI
You’re probably either building a software factory or leasing one from a provider. You have a system that takes you from a prompt to a pull request. It handles tests, linting, formatting, and automated code reviews.
But you still don’t have an answer to the most important question: is this change okay to go to prod?.
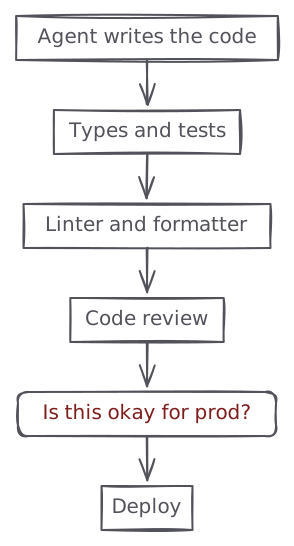
All of your current checks look at the diff, but nothing in your factory knows anything about the production system the diff is about to land on. Nothing can really prevent slop from hitting prod.
We built this capability inside of Polylane and this post is about the technical details of how we implemented it.
How it works
The one questions this system should answer is:
Would this change, once merged and deployed, have a negative impact on production?
We do not really care about the typical things a code-review agent would check such as style, naming, test coverage, etc. And we decided to answer this question at the pull-request stage, along side all your existing tests.
Ultimately, Polylane comments on the pull request with a simple “go” / “no-go” message with the receipts from its investigation.
The flow is fairly simple:
- Is this Pull request touching files that may affect production?
- Which cloud resources are potentially afftected?
- Gather context about the current state of production for those resources
- Evaluate multiple potential failure modes this change may introduce
- Forecast how production might change with these changes deployed
- Alert developers of the likely potential failure modes
Merging this pull request may degrade production (high impact).
Merging this blocks every write to orders while the index builds. migrations/0114_order_search_trgm.sql:3 adds CREATE INDEX … USING gin (search_text gin_trgm_ops) without CONCURRENTLY, and a plain CREATE INDEX takes a full write lock on orders for the whole build. Checkout sustains ~38 writes/s on that table; each one queues behind the lock until the build finishes.
To make this safe: build the index with CREATE INDEX CONCURRENTLY outside the transactional migration.
This all relies on the context graph we continuously build connecting all the cloud resources in your various cloud accounts.
Assembling the context
Our context graph is key to making this work, it builds a registry of all your cloud resources, all your repositories, teams, etc. For instance, a compute node such as Lambda function is connected to the database it reads from and the queue that triggers it. We also add repositories to the graph. This is done by looking at the typical manifest files in the repository, for example terraform files, Cloudformation files or Wrangler files. This enables the connection between repositories and cloud resources.
When a pull request is submitted to the repository, we follow the paths on the context graph to collect all the cloud resources potentially affected by the change. We use a small models to filter through the resources as there could be a large number of resources deployed from the same repository. We pass this context alongside the diff, the PR description and the commits in the PR to the agent.
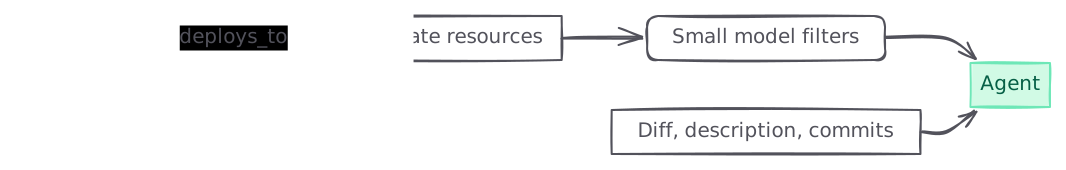
We also pass the diff through a set of deterministic heuristics to quickly guide the agent’s attention towards things that are usually likely to have a negative impact on production:
- a migration that has to be applied by hand, or in a particular order relative to the deploy
CREATE INDEXwithoutCONCURRENTLY, orADD COLUMN ... NOT NULLwith no default, both of which take a lock on the table for the duration- an endpoint being removed while the currently deployed version still reads it
- code that starts reading an environment variable, secret or binding that nothing in the diff provisions
These are recommendations, streering the agent to probably deployment risks.
Failure trajectories
With the context provided above, the model comes up with various failure modes the new diff may introduce in production and goes and investigates each.
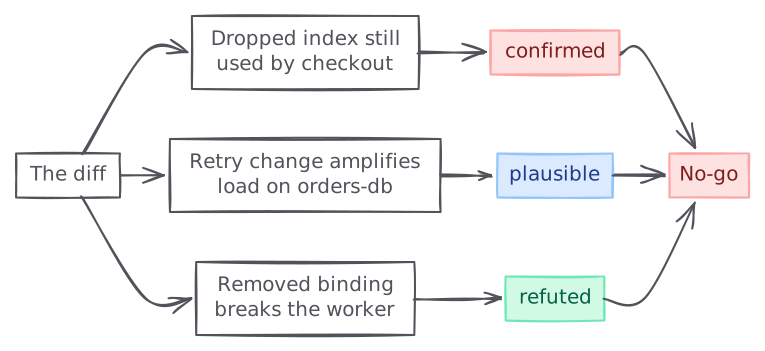
Its output is a ledger of failure trajectories. A trajectory is one causal chain from a trigger, through the changed code, to an observable degradation on a specific metric, and every link in it carries a citation: a file and line, a log template with its count, a metric read, a config key, a graph edge.
The agent tries to both validate and invalidate each trajectory before coming to a verdict. Each ends in one of three states:
confirmedwhen the trajectory has been confirmed against production.plausiblewhen the chain is concrete but one or multiple links could only be “guessed” with no telemetry data to confirm it.refutedwhen production telemetry data provided enough evidence that this trajectory is unlikely to happen in production.
We take a conservative approach and any confirmed trajectory leads to a failed assessment.
export function deriveTrajectoryVerdict(trajectories: Trajectory[]): "pass" | "fail" {
  return trajectories.some((entry) => entry.status === "confirmed") ? "fail" : "pass";
}
Forecasting the impact
We give the agent a tool to forecast timeseries based on historical data with injecting potential external factors.
Say a trajectory claims some change halves the timeout on a path that retries. Whether that matters depends on the traffic, and traffic isn’t really a single number, it has a shape. A queue sitting at 60% depth and staying there is fine. The same queue at 60% but climbing every week is a different situation, and reading the last hour of metrics won’t tell you which one you’re looking at.
So before the agent drafts the verdict of a trajectory, it pulls the historical series for the affected resources and forecasts them together. We currently self-host the Toto-2.0-22m model.
The reason for a dedicated multivariate model rather than another prompt is that the series aren’t independent. Request rate, error rate, latency and queue depth on one resource move together, and forecasting each on its own throws away the correlation that makes the forecast worth having. Every series in a call shares one attention group.
This is the most experimental capability we recently added, and still measuring its impact. But it already passes the vibes-eval.
The latency constraint
Running the production impact assessment in the pull request flow means it must to be fast. Nobody wants a step that adds 15 minutes to their CI pipeline. For instance, on our own repositories this assesment is a required CI step, if it’s slow, our entire SDLC gets bogged down.
We essentially have a budget of 2 to 3 minutes to produce an accurate impact assesment. Anything beyond that is not acceptable in a CI/CD pipeline.
Our first prototype was completely failing this constraint. Our median was nearly 7 minutes and it was common to see runs take up to 20 minutes.
The goal became figuring out how to reduce the number of model steps to get the entire flow under 3 minutes. We typically ran 30 to 40 sequential model steps, and in the worst case scenarios up to nearly 600 steps, each consuming 17 seconds of our budget, and the vast majority of their output was reasoning tokens.
We made quite a few changes over the past 3 weeks, with various impact on performance. Here are the most significant ones.
Setting a step budget and communicating it to the agent
We introduced a step budget, capped at 30 steps by agent turn and we clearly communicate to the model how many steps it has consumed on every step. Putting the count in the prompt lets the model plan around it, which turns out to matter more than the number itself.
Starting new reviews instead of folding into the existing one
A typical pull request keeps getting new commits after it’s opened. In the first prototype, we would fold the entire new diff in the same review thread as a steering user message. This steer would greatly confuse the model and lead to reading files it had already examined and re-running telemetry queries it had already completed.
Now, a new commit cancels the previous assesment run and starts a brand new thread. It seems counter-intuitive, but it ultimately brought down the latency for complete reviews.
Re-using previous work
When a new commit lands in the pull request after a review was already completed, we used to naively start a new impact assessment from scratch.
We introduced the ability to re-use the previous assessment, and trigger a new assesment on the smaller diff between the two consecutive commits.
We deployed these changes throughout September and have gradually improved latency and the latency comfortably sits within budget.
Does this even matter?
What’s the point of burning all these tokens if we don’t see any meaningful results? Our success metric is the number of incidents we prevent per week for each of our customers. A prevented incident is a pull request where:
- we flag a potential risk to production
- an engineer pushes one or multiple commits
- a new assessment concludes the potential risk is mitigated
- the pull request gets merged
This is already pretty significant and we expect this to keep growing. We are continously iterating and running evals to improve the performance and quality of our agent.