

Sub-agents are just wrong
Explore with AI
Polylane’s autofix agent was originally built as a workflow of multiple sub-agents, each responsible for a single task:
- a triage to sort through thousands of alerts and signals
- a coordinator to operate sub-agents
- up to fifteen sub-agents to investigate all possible hypotheses for the issue
- and a coding agent to ultimately submite a pull request
A confirmed issue could lead to up to 18 agents and sub-agents for the investigation and the fix. Today the same work is done by a single agent.
The workflow was a sound design based on what we knew at the time: small prompts, small tool sets, an orchestrator to carry results between specialists. It was however extremely expensive and difficult to operate and reason about.
What is an issue?
Polylane scans logs, metrics and traces from every cloud resource (Lambda function, Cloudflare Worker, Vercel project, etc.) on every connected provider. For each resource we store baselines across multiple horizons, such that we can capture seasonality in the data. We then assess the current state of the cloud resource and compare it with historical data. Values that break the baseline are recorded as issues.
Issues can also be created by alerts we receive from observability and error tracking solutions.
How do we resolve issues?
To resolve an issue, we need to:
- Triage: Gather data to confirm or reject the issue.
- Investigate: Assess multiple hypotheses and determine the root cause.
- Open a pull request or escalate. Either write a pull request to resolve the issue, escalate to an engineer if the fix is not a code change, or write a report highlighting the findings and stop.
The vast majority of runs terminate before a pull request or an escalation, when Polylane concludes the issue is either a false positive or benign.
Sub-agents architecture
Our initial architecture was based on multiple sub-agents.
We used an orchestrator agent to cordinate work between multiple sub-agents. Sub-agents were instanciated to investigate hypotheses, trying to prove or disprove each hypothesis with different starting points (for example starting by looking at the logs, or starting with the codebase, etc.).
The findings of the sub-agents were voted with simple arithmetic and summarised by another agent before being rolled up to the coordinator agent.
Each hypothesis’s verdict was a confidence-weighted vote across its passes.
const CONFIDENCE_RANK = { definitive: 4, strong: 3, moderate: 2, weak: 1, speculative: 0 };

function aggregatePassVerdicts(passes: PassResult[]): Verdict {
  const weights: Record<string, number> = {};
  const counts: Record<string, number> = {};
  for (const p of passes) {
    weights[p.verdict] = (weights[p.verdict] ?? 0) + CONFIDENCE_RANK[p.confidence];
    counts[p.verdict] = (counts[p.verdict] ?? 0) + 1;
  }
  const totalWeight = Object.values(weights).reduce((a, b) => a + b, 0);
  const [winner, winnerWeight] = Object.entries(weights).sort((a, b) => b[1] - a[1])[0];

  const countMajority = counts[winner] > passes.length / 2;
  const weightMajority = winnerWeight > totalWeight / 2;
  if (!countMajority && !weightMajority) {
    return { verdict: "inconclusive", confidence: "weak", summary: `No consensus across ${passes.length} passes.` };
  }

  const majority = passes.filter((p) => p.verdict === winner);
  const confidence = majority.reduce((min, p) => (CONFIDENCE_RANK[p.confidence] < CONFIDENCE_RANK[min] ? p.confidence : min), majority[0].confidence);
  const lead = majority.reduce((best, p) => (CONFIDENCE_RANK[p.confidence] > CONFIDENCE_RANK[best.confidence] ? p : best));
  return { verdict: winner, confidence, summary: lead.summary };
}
Once all hypotheses were investigated, if a root cause was identified, the coordinator would either escalate to an engineer or write a plan for the fix. This plan would be handed to a coding sub-agent to implement the fix and submit the pull request.
The main issue in this architecture is the context loss between sub-agents. Each agent was passing up or down just fractions of their context, through summarization, and both upstream and downstream agents regularly had to redo the same work.
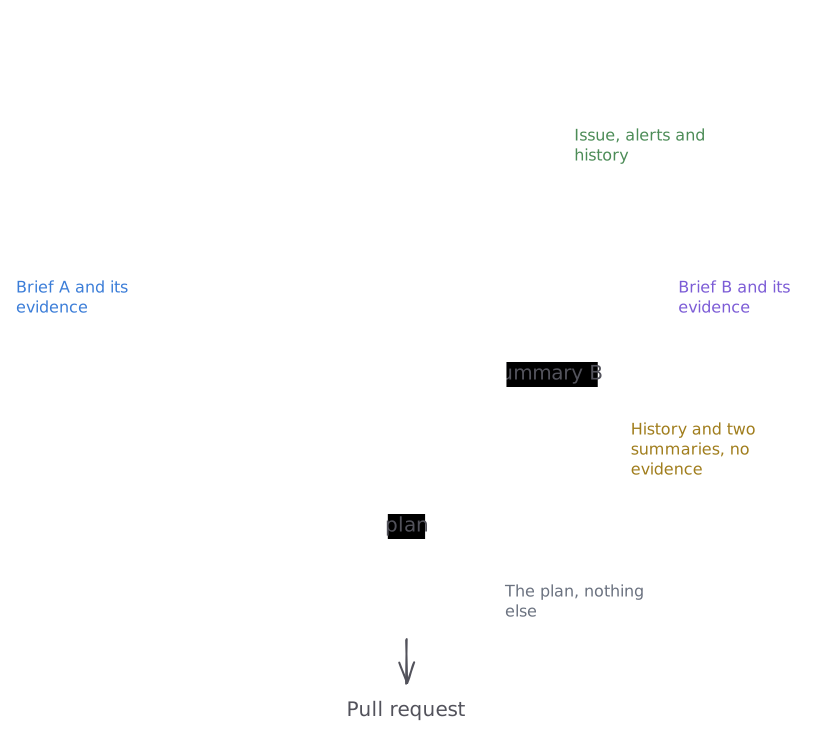
Moreover, the agent writing the fix only had the plan, lacking context on the original issue or the evidence collected in the investigation. This led to sub-par pull requests which often focused on symptoms rather than the root cause.
We chose this architecture primarily because when we first designed it in March 2026, frontier models were not always capable of running an investigation end-to-end, including writing the fix, and also plainly, our harness was not that good.
It became increasingly harder to build on this foundation because:
- Debugging took many traces. Reasoning around an end-to-end investigation required looking through multiple, sometimes dozens of traces
- Evaluation was per stage. Each sub-agent could be evaluated individually and pass, while the end result was poor, because the failures lived in the handoffs.
We iterated on this architecture for months, improving each agent individually and tweaking the prompts and the handoffs, but the results never matched the effort. It was expensive, hard to debug, and the pull requests were not good enough.
Single agent
On Sept 3, we replaced the sub-agents workflow with a single agent doing everything from triage to pull request. The same agent collects the evidence, investigates all the hypotheses, and submits the pull request.
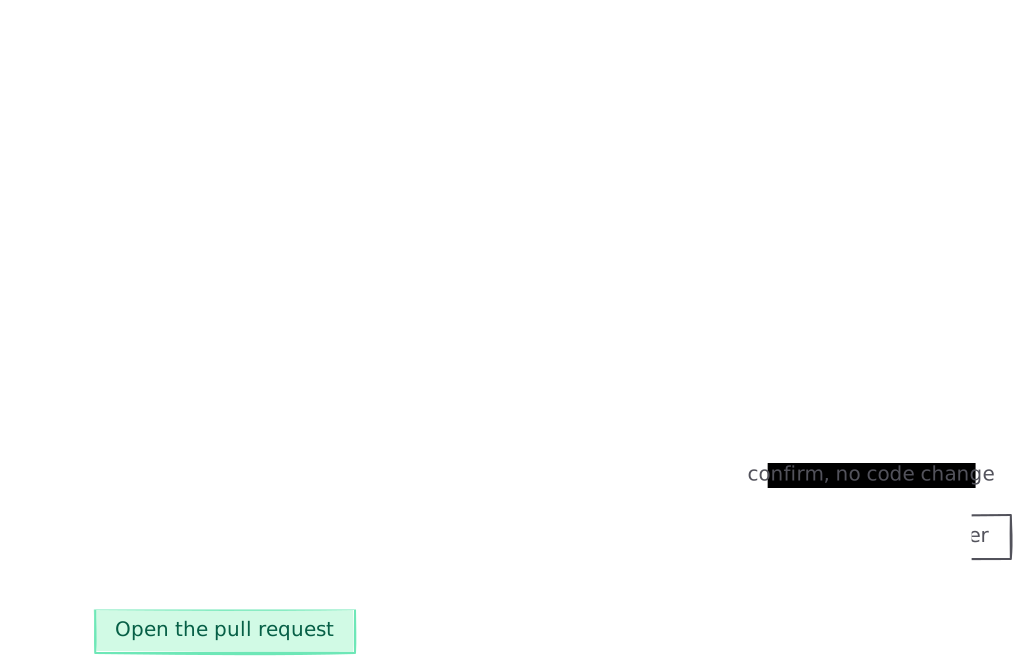
We deleted the triage agent, the coordinator, the hypothesis agents, and the autofix agent, along with the workflows that carried results between them and the gates that sat in front of the pull request. The operational benefits were immediate: one trace to evaluate, and no summaries between sub-agents.
More importantly, the quality of the pull requests improved, and the time between detecting an issue and opening the pull request that fixes it collapsed. Over the month around the cutover, the median went from 2.2 hours to 35 minutes and the p90 from nine days to under two hours. Under the pipeline a finding typically sat for multiple hours in a chain of workflows, each waiting on the last. Under the single agent, the pull request opens just minutes after the issue is detected.
We now also open far more pull requests. When we were using sub-agents, 0.6% of detected issues ended in a pull request. Under the single agent it is 4.2%, and rising. The difference is failure modes. A pipeline with multiple sub-agents has to survive every handoff: triage has to promote the finding, the coordinator has to produce hypotheses, the fan-out has to reach a verdict, etc. Each handoff is a potential failure mode.
Cost per pull request fell as well. Every run now starts on the stronger model, so a dismissed finding costs more than it did under the pipeline. But, the average cost per pull request went from $111 to about $18 in the first nine days of the single agent. This drop is not exclusively the result of the change in architecture, as we’re actively iterating on every aspect of Polylane. Some of it is the ordinary drift of a system under constant iteration.
Every value behind the three charts, by UTC day
| Day | Detected issues with a pull request | Median | p90 | Spend per pull request |
|---|---|---|---|---|
| 14 Aug | 1.9% | 2.3 h | 2.7 h | $144 |
| 15 Aug | 1.1% | 5.6 h | 5.9 h | $270 |
| 16 Aug | 2.3% | 1.2 h | 4.2 d | $121 |
| 17 Aug | 1.5% | 38 min | 4.5 d | $120 |
| 18 Aug | 0.9% | 20 min | 27 min | $57 |
| 19 Aug | 0.7% | 49 min | 12.2 h | $157 |
| 20 Aug | 0.7% | 1 h | 35.9 h | $202 |
| 21 Aug | 0.8% | 44.2 h | 4.2 d | $211 |
| 22 Aug | 0.8% | 7.7 d | 10.4 d | $563 |
| 23 Aug | 1.3% | 32 min | 35.3 h | $205 |
| 24 Aug | 0.6% | 2.5 d | 5.6 d | $90 |
| 25 Aug | 1.4% | 1.5 h | 13.4 h | $43 |
| 26 Aug | 0.3% | 1.5 h | 2.1 h | $45 |
| 27 Aug | 0.7% | 1.9 h | 2.5 h | $58 |
| 28 Aug | 1% | 11.7 d | 14.1 d | $49 |
| 29 Aug | 1.5% | 26.1 h | 10.4 d | $32 |
| 30 Aug | 0.5% | 2 d | 2.8 d | $51 |
| 31 Aug | 0.2% | 9 d | 10.4 d | $77 |
| 1 Sep | 0.1% | 4.2 d | 4.2 d | $169 |
| 2 Sep | 0.1% | 6.7 d | 6.7 d | $93 |
| 3 Sep · one agent | 0.4% | 29 min | 2.6 d | $69 |
| 4 Sep | 2.4% | 23 min | 5.4 h | $25 |
| 5 Sep | 2.9% | 34 min | 3.4 d | $15 |
| 6 Sep | 1.4% | 34 min | 43.7 h | $23 |
| 7 Sep | 1.8% | 32 min | 4.5 h | $16 |
| 8 Sep | 4% | 41 min | 19.4 h | $26 |
| 9 Sep | 7.6% | 34 min | 1.2 h | $15 |
| 10 Sep | 5% | 34 min | 1.3 h | $17 |
| 11 Sep | 5.4% | 56 min | 2.1 h | $12 |
| 12 Sep | 9.1% | 35 min | 1.3 h | $3.46 |
| 13 Sep · to 16:00 | 8.2% | 30 min | 55 min | $2.88 |
Don’t build sub-agents
- Handoffs lose more than they save. Every summary passed between agents is context the next agent will never have. The agent that gathers the evidence should be the agent that acts on it.
- Evaluate the run, not the agents. Per-agent evaluations pass while the system fails, because the failures live between the agents.
- Keep one trace per run. A wrong decision spread across a dozen traces takes an afternoon to explain. In one trace it takes a scroll.