

子智能体就是错的
Explore with AI
Polylane的autofix智能体最初被构建为由多个子智能体组成的工作流,每个子智能体负责单一任务:
- 一个分诊智能体,用于筛选成千上万条告警和信号
- 一个协调智能体,用于操作各个子智能体
- 最多十五个子智能体,用于调查该问题的所有可能假设
- 以及一个编程智能体,用于最终提交拉取请求
一个已确认的问题可能会调用多达18个智能体和子智能体来进行调查和修复。如今,同样的工作由单个智能体完成。
这个工作流是基于我们当时所了解信息而做出的合理设计:小型提示词、小型工具集,以及一个在各专业智能体之间传递结果的编排智能体。然而,它的运行成本极高,也很难运维和推理。
什么是问题?
Polylane会扫描每个已连接提供商上每个云资源(Lambda函数、Cloudflare Worker、Vercel项目等)的日志、指标和追踪数据。对于每个资源,我们会存储跨多个时间跨度的基线,从而能够捕捉数据中的季节性规律。然后我们会评估云资源的当前状态,并将其与历史数据进行比较。突破基线的数值会被记录为问题。
问题也可以由我们从可观测性和错误追踪解决方案接收到的告警创建。
我们如何解决问题?
要解决一个问题,我们需要:
- 分诊: 收集数据以确认或否定该问题。
- 调查: 评估多个假设并确定根因。
- 开启拉取请求或上报。 编写用于解决问题的拉取请求,如果修复不属于代码变更就上报给工程师,或者撰写一份说明调查结果的报告并停止。
绝大多数运行会在提交拉取请求或上报之前终止,此时Polylane判定该问题要么是误报,要么是良性的。
子智能体架构
我们最初的架构基于多个子智能体。
我们使用一个编排智能体来协调多个子智能体之间的工作。子智能体被实例化来调查各个假设,尝试从不同的起点(例如从查看日志开始,或从代码库开始等)来证实或证伪每个假设。
子智能体的调查结果通过简单的算术方式进行投票,并由另一个智能体进行汇总,然后再汇总给协调智能体。
每个假设的判定结果,都是其各轮次结果按置信度加权投票得出的。
const CONFIDENCE_RANK = { definitive: 4, strong: 3, moderate: 2, weak: 1, speculative: 0 };

function aggregatePassVerdicts(passes: PassResult[]): Verdict {
  const weights: Record<string, number> = {};
  const counts: Record<string, number> = {};
  for (const p of passes) {
    weights[p.verdict] = (weights[p.verdict] ?? 0) + CONFIDENCE_RANK[p.confidence];
    counts[p.verdict] = (counts[p.verdict] ?? 0) + 1;
  }
  const totalWeight = Object.values(weights).reduce((a, b) => a + b, 0);
  const [winner, winnerWeight] = Object.entries(weights).sort((a, b) => b[1] - a[1])[0];

  const countMajority = counts[winner] > passes.length / 2;
  const weightMajority = winnerWeight > totalWeight / 2;
  if (!countMajority && !weightMajority) {
    return { verdict: "inconclusive", confidence: "weak", summary: `No consensus across ${passes.length} passes.` };
  }

  const majority = passes.filter((p) => p.verdict === winner);
  const confidence = majority.reduce((min, p) => (CONFIDENCE_RANK[p.confidence] < CONFIDENCE_RANK[min] ? p.confidence : min), majority[0].confidence);
  const lead = majority.reduce((best, p) => (CONFIDENCE_RANK[p.confidence] > CONFIDENCE_RANK[best.confidence] ? p : best));
  return { verdict: winner, confidence, summary: lead.summary };
}
一旦所有假设都调查完毕,如果确定了根因,协调智能体要么上报给工程师,要么撰写一份修复计划。这份计划会被交给一个编程子智能体来实施修复并提交拉取请求。
这种架构的主要问题在于子智能体之间的上下文丢失。每个智能体都只能通过摘要向上或向下传递自己一小部分上下文,导致上游和下游的智能体经常需要重复做同样的工作。
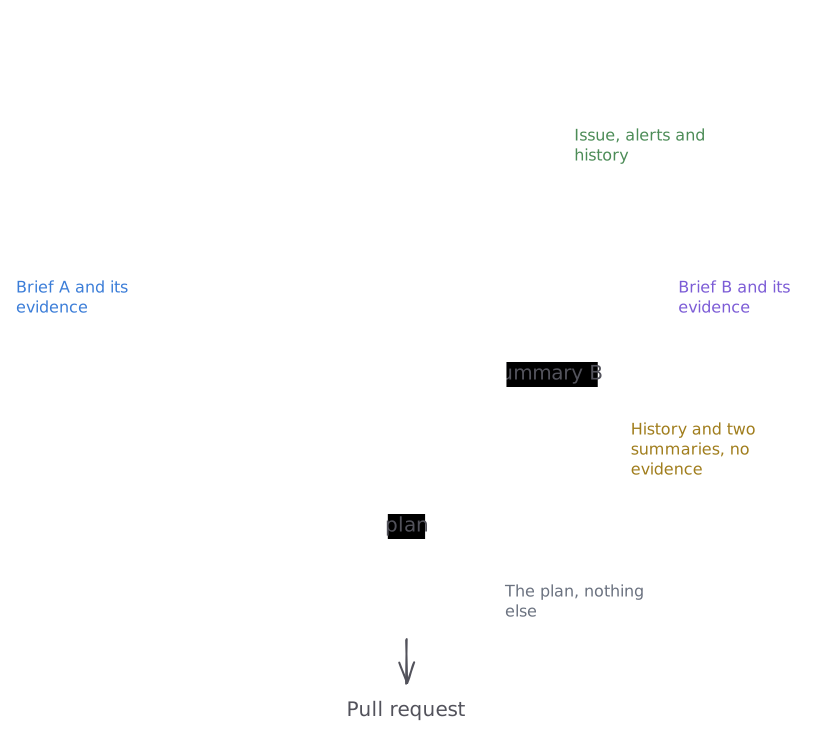
此外,负责编写修复方案的智能体只拿到了这份计划,缺乏关于原始问题或调查过程中收集到的证据的上下文。这导致提交的拉取请求质量欠佳,往往只针对表面症状,而非根因。
我们之所以选择这种架构,主要是因为在2026年3月首次设计它时,前沿模型并不总能端到端地完成一次调查(包括编写修复方案),而且坦白说,我们的harness当时也不够好。
在这个基础上继续构建变得越来越困难,原因是:
- 调试需要查看大量追踪记录。 要推理出一次端到端的调查过程,需要查看多条、有时甚至是几十条追踪记录
- 评估是按阶段进行的。 每个子智能体都可以单独评估并通过,但最终结果却很差,因为失败往往发生在交接环节。
我们在这种架构上迭代了数月,逐个改进各个智能体,并调整提示词和交接环节,但结果始终配不上投入的努力。它成本高昂、难以调试,提交的拉取请求也不够好。
单一智能体
9月3日,我们用一个单一智能体取代了子智能体工作流,由它完成从分诊到拉取请求的全部工作。同一个智能体收集证据、调查所有假设,并提交拉取请求。
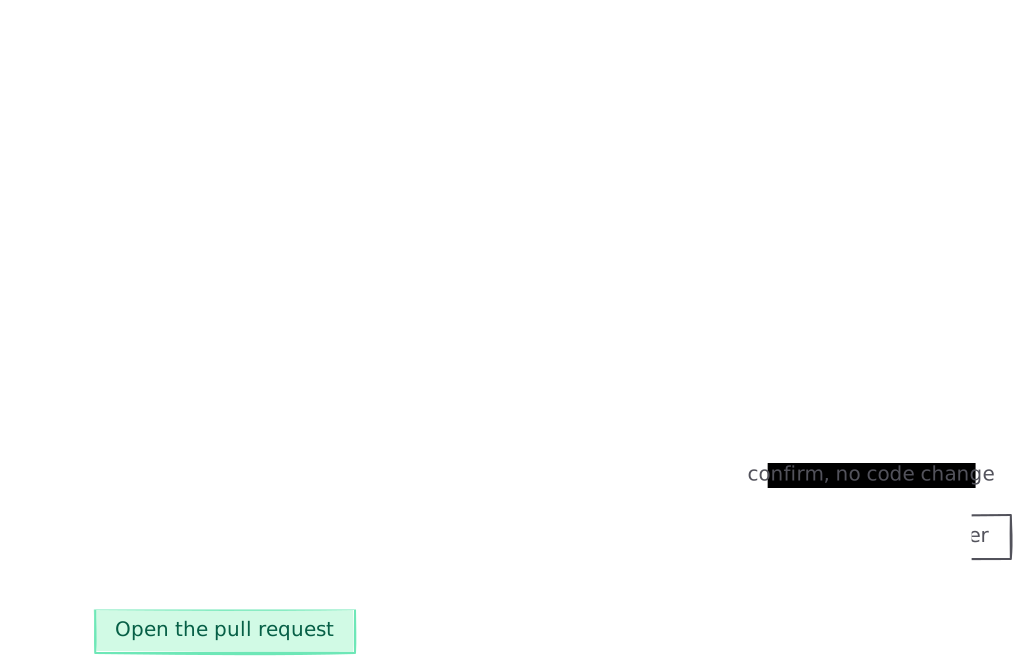
我们删除了分诊智能体、协调智能体、假设智能体和autofix智能体,以及在它们之间传递结果的工作流,还有位于拉取请求之前的各个关卡。运维上的收益立竿见影:只需评估一条追踪记录,子智能体之间也不再需要摘要。
更重要的是,拉取请求的质量提高了,从检测到问题到开启修复它的拉取请求之间所耗费的时间大幅缩短。在切换前后的那个月里,中位数从2.2小时降到了35分钟,p90从9天降到了不到2小时。在流水线架构下,一项调查发现通常要在一连串相互等待的工作流中停留数小时。而在单一智能体架构下,拉取请求会在问题被检测到后的几分钟内开启。
如今我们提交的拉取请求也大幅增多。在使用子智能体时,只有0.6%被检测出的问题最终会形成拉取请求。在单一智能体架构下,这一比例是4.2%,并且还在上升。差异在于失败模式。一个由多个子智能体组成的流水线,必须在每一次交接中都存活下来:分诊必须推进这项发现,协调智能体必须产出假设,扇出调查必须得出一个判定结果,等等。每一次交接都是一个潜在的失败点。
每个拉取请求的成本也下降了。现在每次运行都从更强的模型开始,因此一项被驳回的发现,其成本要比在流水线架构下更高。但是,在单一智能体上线的头9天里,每个拉取请求的平均成本从$111降到了约$18。这一下降并非完全是架构变更的结果,因为我们也在持续迭代Polylane的方方面面。其中一部分只是一个持续迭代中的系统所常见的正常波动。
按UTC日期列出的三张图表背后的全部数值
| 日期 | 带有拉取请求的已检测问题 | 中位数 | p90 | 每个拉取请求的花费 |
|---|---|---|---|---|
| 14 Aug | 1.9% | 2.3 h | 2.7 h | $144 |
| 15 Aug | 1.1% | 5.6 h | 5.9 h | $270 |
| 16 Aug | 2.3% | 1.2 h | 4.2 d | $121 |
| 17 Aug | 1.5% | 38 min | 4.5 d | $120 |
| 18 Aug | 0.9% | 20 min | 27 min | $57 |
| 19 Aug | 0.7% | 49 min | 12.2 h | $157 |
| 20 Aug | 0.7% | 1 h | 35.9 h | $202 |
| 21 Aug | 0.8% | 44.2 h | 4.2 d | $211 |
| 22 Aug | 0.8% | 7.7 d | 10.4 d | $563 |
| 23 Aug | 1.3% | 32 min | 35.3 h | $205 |
| 24 Aug | 0.6% | 2.5 d | 5.6 d | $90 |
| 25 Aug | 1.4% | 1.5 h | 13.4 h | $43 |
| 26 Aug | 0.3% | 1.5 h | 2.1 h | $45 |
| 27 Aug | 0.7% | 1.9 h | 2.5 h | $58 |
| 28 Aug | 1% | 11.7 d | 14.1 d | $49 |
| 29 Aug | 1.5% | 26.1 h | 10.4 d | $32 |
| 30 Aug | 0.5% | 2 d | 2.8 d | $51 |
| 31 Aug | 0.2% | 9 d | 10.4 d | $77 |
| 1 Sep | 0.1% | 4.2 d | 4.2 d | $169 |
| 2 Sep | 0.1% | 6.7 d | 6.7 d | $93 |
| 3 Sep · 单一智能体 | 0.4% | 29 min | 2.6 d | $69 |
| 4 Sep | 2.4% | 23 min | 5.4 h | $25 |
| 5 Sep | 2.9% | 34 min | 3.4 d | $15 |
| 6 Sep | 1.4% | 34 min | 43.7 h | $23 |
| 7 Sep | 1.8% | 32 min | 4.5 h | $16 |
| 8 Sep | 4% | 41 min | 19.4 h | $26 |
| 9 Sep | 7.6% | 34 min | 1.2 h | $15 |
| 10 Sep | 5% | 34 min | 1.3 h | $17 |
| 11 Sep | 5.4% | 56 min | 2.1 h | $12 |
| 12 Sep | 9.1% | 35 min | 1.3 h | $3.46 |
| 13 Sep · 截至16:00 | 8.2% | 30 min | 55 min | $2.88 |
不要构建子智能体
- 交接的损失大于收益。 智能体之间传递的每一份摘要,都是下一个智能体永远无法获得的上下文。收集证据的智能体,应该就是采取行动的智能体。
- 要评估整个运行过程,而不是各个智能体。 逐个智能体的评估可以通过,但整个系统却会失败,因为失败发生在智能体之间。
- 每次运行只保留一条追踪记录。 一个分散在十几条追踪记录中的错误决策,需要花一下午时间来解释清楚。而在一条追踪记录里,只需要滚动查看即可。