 Boris Tane
Kubernetes CrashLoopBackOff: causes and fixes
Explore with AI
CrashLoopBackOffCrashLoopBackOff means a container in the pod keeps exiting and the kubelet is waiting before it restarts it again, with a delay that starts at 10 seconds and doubles up to 5 minutes. It is a symptom: the cause is in the container's last exit. Run kubectl logs --previous and kubectl describe pod, read the Last State reason and exit code, then fix the app error, config, memory limit, probe or command it points to.
You run kubectl get pods and one row says CrashLoopBackOff. READY is 0/1, the RESTARTS count keeps climbing, and the pod never serves traffic. If a rollout started it, the rollout stalls while the old pods keep serving.
CrashLoopBackOff is a waiting state. It tells you the container has exited several times and the kubelet is holding off before the next restart. It doesn’t tell you why the container exits. That answer sits in the previous container’s logs, its exit code and the pod’s events, and this page shows you how to read each one.
What CrashLoopBackOff means
The kubelet on the node prints it. When a container exits and the pod’s restartPolicy allows a restart, the kubelet restarts it in the same pod on the same node. If it exits again, the kubelet applies an exponential back-off before each new attempt. The Pod Lifecycle docs give the defaults: 10s, 20s, 40s and so on, capped at 300 seconds (5 minutes). Once a container has run for 10 minutes without problems, the kubelet resets the timer.
While the timer runs, the container sits in the Waiting state with the reason CrashLoopBackOff, and that reason is what kubectl shows in STATUS. The pod’s phase stays Running. The docs call STATUS “a kubectl display field for user intuition” and warn you not to confuse it with the phase.
You’ll see the same state in three places. In the kubelet source, doBackOff records a Warning event with the reason BackOff:
Warning BackOff 12s (x8 over 2m) kubelet Back-off restarting failed container api in pod api-7d9c_default(3f1b...)It also sets the container’s waiting message to the current delay, which reads like this once the cap is reached:
back-off 5m0s restarting failed container=api pod=api-7d9c_default(3f1b...)And it returns the error CrashLoopBackOff, which is the reason you see in kubectl describe pod under State: Waiting.
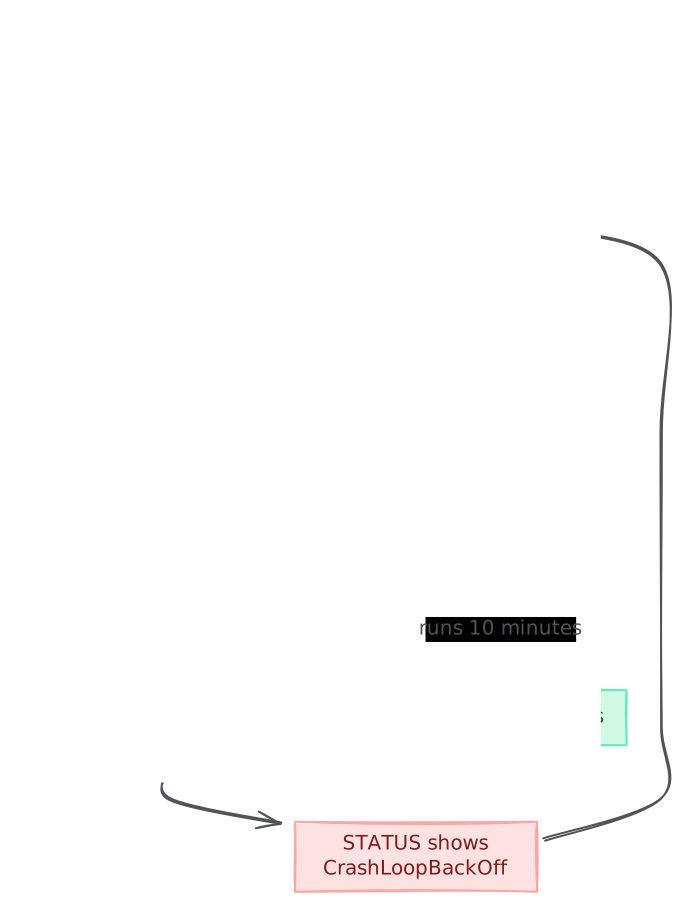
The delay explains why a crash loop feels slow to debug. After a few failures, each new attempt is up to 5 minutes away, so a fix you apply by hand can look like it did nothing for a while.
Changing the back-off on newer clusters
Two kubelet features change these numbers. Neither fixes a crash, but they change how long you wait between attempts.
- KubeletCrashLoopBackOffMax, beta and enabled by default since v1.35. You set
maxContainerRestartPeriodundercrashLoopBackOffin the kubelet configuration, between"1s"and"300s", per node. Delays still start at 10s and double, but stop at your cap. A cap under 10s becomes the starting delay too. - ReduceDefaultCrashLoopBackOffDecay, alpha since v1.33 and off by default. With it on, restarts start at 1s and cap at 60s across the cluster. A node’s own
maxContainerRestartPeriodwins over these defaults.
kind: KubeletConfiguration
crashLoopBackOff:
  maxContainerRestartPeriod: "100s"
Reading the last exit before you change anything
Every cause below leaves a different trace. Collect three things first.
- The logs of the container that crashed. Plain
kubectl logsreads the current instance, which may be waiting and empty.--previousreads the one that died:kubectl logs <pod> -c <container> --previous - The container’s last state and the pod’s events:
Look atkubectl describe pod <pod>Last State: Terminated, itsReasonandExit Code, then the Events table at the bottom. - The events on their own, if the describe output is long:
kubectl events --for pod/<pod>
kubectl get events --field-selector involvedObject.name=<pod>
The API server keeps events for one hour by default: the kube-apiserver flag --event-ttl defaults to 1h0m0s. The Last State in the container status survives longer, so read it even when the events are gone.
The exit code narrows the search fast. The Bash manual says a process killed by signal N reports 128 plus N, a command that isn’t found reports 127, and one that isn’t executable reports 126. So 137 means SIGKILL (9) and 143 means SIGTERM (15).
Why the container keeps exiting
The Pod Lifecycle docs list the usual causes: application errors that make the container exit, configuration errors such as wrong environment variables or missing files, resource constraints, and liveness or startup probes that fail. Here they are with the trace each one leaves, most common first.
Cause 1: the application exits on startup
How to tell it’s yours: Last State shows Reason: Error and a small non-zero exit code, often 1. kubectl logs --previous ends with a stack trace, a panic or a message such as a failed database connection. The Debug Running Pods guide shows exactly this shape:
State:          Waiting
  Reason:       CrashLoopBackOff
Last State:     Terminated
  Reason:       Error
  Exit Code:    1
Fix:
- Read the end of the previous logs. The last lines before the exit usually name the problem.
- If the app exits before it logs anything, make Kubernetes keep its last output. With
terminationMessagePolicy: FallbackToLogsOnError, the kubelet copies the last chunk of the log into the termination message when the container exits with an error, limited to 2048 bytes or 80 lines:
Then read it from the pod status:containers: - name: api image: registry.example.com/api:1.4.2 terminationMessagePolicy: FallbackToLogsOnErrorkubectl get pod <pod> -o go-template='{{range .status.containerStatuses}}{{.lastState.terminated.message}}{{end}}' - If a deploy started the loop, roll back first and debug second:
To go back to a specific revision, addkubectl rollout history deployment/api kubectl rollout undo deployment/api kubectl rollout status deployment/api--to-revision=2. - Reproduce it outside the cluster. The docs suggest running the same image locally, for example with
docker run --rm registry.example.com/api:1.4.2, using the same environment variables the pod gets.
Cause 2: bad configuration, environment variables or secrets
How to tell it’s yours: the same image runs fine elsewhere, and the previous logs complain about a missing variable, an unreadable file or a value that doesn’t parse. Often the crash started right after a change to a ConfigMap, a Secret or the Deployment’s env.
Fix:
- Compare what the pod gets with what the app expects:
kubectl get pod <pod> -o jsonpath='{.spec.containers[0].env}' kubectl get pod <pod> -o jsonpath='{.spec.containers[0].envFrom}' kubectl describe configmap <name> - If the app has no shell to inspect, start a copy of the pod with the command replaced by one, as the debug guide shows. The
--containerflag replaces that container’s command:
Inside, runkubectl debug <pod> -it --copy-to=<pod>-debug --container=api -- shenv, check the mounted files and start the app by hand to watch it fail. - Fix the ConfigMap, Secret or
enventry, then restart the Deployment so new pods pick it up:kubectl rollout restart deployment/api - Delete the debug copy when you’re done:
kubectl delete pod <pod>-debug.
Cause 3: the container runs out of memory
How to tell it’s yours: Last State shows Reason: OOMKilled and Exit Code: 137. The previous logs often stop mid-line, because the kernel killed the process without warning.
The container used more memory than its limit, and the kernel killed it. Each restart climbs back to the same usage and dies again, which turns into a crash loop. The fix is either a higher limit or a smaller footprint, and the OOMKilled page covers both: reading kubectl top pod --containers, sizing requests and limits, and matching Node.js or JVM heap flags to the limit.
Cause 4: a failing liveness or startup probe
How to tell it’s yours: the logs look healthy, then the container stops. The Events show Unhealthy warnings followed by Killing. The probes guide shows the pattern:
Warning  Unhealthy  10s (x3 over 20s)  kubelet  Liveness probe failed: cat: can't open '/tmp/healthy': No such file or directory
Normal   Killing    10s                kubelet  Container liveness failed liveness probe, will be restarted
When a liveness or startup probe fails, the kubelet kills the container and applies the restart policy. A slow-starting app with a tight liveness probe gets killed during startup, every time, and loops. Probe timeoutSeconds defaults to 1 second, which is short for an endpoint that touches a database.
Fix:
- Check what the probe hits and whether the app answers in time:
kubectl get pod <pod> -o jsonpath='{.spec.containers[0].livenessProbe}' - Add a startup probe that covers the slowest start you expect. Liveness and readiness probes don’t run until it succeeds. The docs give this example, which allows up to 30 × 10 = 300 seconds to start:
ports: - name: liveness-port containerPort: 8080 livenessProbe: httpGet: path: /healthz port: liveness-port failureThreshold: 1 periodSeconds: 10 startupProbe: httpGet: path: /healthz port: liveness-port failureThreshold: 30 periodSeconds: 10 - Keep the liveness endpoint cheap. It should answer whether this process can make progress. A check that calls a database or another service fails when that dependency is slow, and the kubelet restarts healthy containers as a result.
- If the startup probe never succeeds, the container is killed after its window and the loop goes on. In that case the problem is the app, so go back to cause 1.
Cause 5: the wrong command or entrypoint
How to tell it’s yours: the container exits at once with no app logs at all. With a shell entrypoint, the exit code is 127 (command not found) or 126 (found but not executable). If the binary named in command doesn’t exist in the image, the process never starts: read the Last State message and the Events for the container runtime’s error.
Common triggers are a command that overrides the image’s ENTRYPOINT with a wrong path, a script without execute permission, and a multi-stage build that left the binary out of the final image.
Fix:
- Compare the pod’s
commandandargswith the image:kubectl get pod <pod> -o jsonpath='{.spec.containers[0].command} {.spec.containers[0].args}' docker image inspect registry.example.com/api:1.4.2 --format '{{.Config.Entrypoint}} {{.Config.Cmd}}' - Open the image with a shell and look for the file:
kubectl debug <pod> -it --copy-to=<pod>-debug --container=api -- sh ls -l /app - For an image with no shell, attach an ephemeral debug container.
--targetpoints it at the process namespace of the named container, and the runtime has to support it:kubectl debug -it <pod> --image=busybox:1.28 --target=api - Fix the path or permissions in the manifest or Dockerfile (
RUN chmod +x /app/start.sh), rebuild and redeploy.
Confirming the crash loop is over
A single successful start proves little, because the container might crash again a minute later. Watch it:
kubectl get pod <pod> -wExpected output once it’s fixed:
NAME        READY   STATUS    RESTARTS      AGE
api-7d9c    1/1     Running   6 (12m ago)   31m
Two signs matter. READY shows 1/1, so the readiness probe passes. And the RESTARTS count stays flat for more than 10 minutes. That is the point where the kubelet resets the back-off timer, so the container has now run long enough to count as healthy. For a Deployment, kubectl rollout status deployment/api should report that the rollout finished.
Stopping CrashLoopBackOff from coming back
- Set a rollout deadline.
.spec.progressDeadlineSecondsdefaults to 600. When a new version crash-loops, the Deployment gets aProgressingcondition with reasonProgressDeadlineExceeded. Kubernetes only reports it, so alert on it or have your deploy tool roll back. - Give slow starters a startup probe sized from a measured worst case, and keep liveness checks local to the process.
- Validate config at startup and say what’s missing. An app that logs
DATABASE_URL is not setbefore it exits turns a 20-minute hunt into a one-line fix. - Turn on
FallbackToLogsOnErrorfor containers that can die before their logging is up. - Alert on restarts. A container that restarts a few times an hour never shows CrashLoopBackOff for long, yet it is still failing. Alert on the restart count rising over a window, along with the status.
- Ship events somewhere that keeps them. With a one-hour default TTL, the evidence for an overnight crash loop is gone by morning.
The habit worth keeping is simple: look at the last exit, the last logs and the events together. With those three side by side, most crash loops take minutes.
Tracing a crash loop back to its cause with Polylane
Polylane connects a cluster through an agent you install with Helm, with read-only RBAC limited to get, list and watch. Its agents inspect pods, deployments and nodes and read logs and events, so a crash loop is investigated from the same evidence this page uses, starting from the rollout that came before it.
Running on Kubernetes? See how Polylane monitors Kubernetes in production.
Common questions.
How long does Kubernetes wait between restarts in CrashLoopBackOff?
By default the kubelet waits 10 seconds after the first crash, then 20, then 40, doubling each time up to a cap of 300 seconds (5 minutes). Once a container has run for 10 minutes without problems, the kubelet resets the timer and the next crash counts as the first one.
Can I shorten the CrashLoopBackOff delay?
Yes, per node. The KubeletCrashLoopBackOffMax feature is beta and on by default since Kubernetes v1.35, so you can set crashLoopBackOff.maxContainerRestartPeriod in the kubelet configuration to anything from 1s to 300s. A separate alpha gate, ReduceDefaultCrashLoopBackOffDecay, changes the cluster defaults to a 1 second start and a 60 second cap, and it is off by default.
Is CrashLoopBackOff a pod phase?
No. It shows in the STATUS column of kubectl get pods and as the Waiting reason of a container, but the pod's phase is usually still Running. The Kubernetes docs warn against confusing that kubectl display field with the phase in the Pod API.
Why does kubectl logs show nothing for my crashing pod?
Plain kubectl logs reads the current container, which may be waiting in back-off and has printed nothing yet. Add --previous (or -p) to read the instance that crashed, and -c with the container name in a multi-container pod. If the app dies before it logs anything, set terminationMessagePolicy to FallbackToLogsOnError so the last 80 lines or 2048 bytes land in the pod status.
What does exit code 137 mean in CrashLoopBackOff?
137 is 128 plus 9, the number of SIGKILL. If the Last State reason is OOMKilled, the container went over its memory limit. If the reason is Error and the events show a failed liveness or startup probe, the kubelet killed it after the probe failed.
My events are gone. How do I find out what happened?
The API server keeps events for one hour by default (the kube-apiserver --event-ttl flag defaults to 1h0m0s). The container status still holds the last termination reason, exit code and message, so kubectl describe pod and kubectl get pod -o yaml still show Last State after the events expire.
Should I just delete the pod?
Deleting it makes the Deployment create a new pod with a fresh back-off timer, but the new container hits the same cause and loops again. Delete only after you've changed something: the image, the config, the limit or the probe.
How do I roll back a deploy that started the crash loop?
Run kubectl rollout history deployment/<name> to see the revisions, then kubectl rollout undo deployment/<name>, or add --to-revision=<n> for a specific one. Watch it with kubectl rollout status deployment/<name>.
Sources
- Pod Lifecycle (Kubernetes docs)
- kuberuntime_manager.go, doBackOff (Kubernetes source)
- kubelet.go, crash loop back-off defaults (Kubernetes source)
- Debug Running Pods (Kubernetes docs)
- Configure Liveness, Readiness and Startup Probes (Kubernetes docs)
- Determine the Reason for Pod Failure (Kubernetes docs)
- Deployments (Kubernetes docs)
- kubectl events (Kubernetes docs)
- kube-apiserver reference (Kubernetes docs)
- kubectl rollout restart (Kubernetes docs)
- signal(7), Linux manual page
- Exit Status (GNU Bash manual)
- Kubernetes integration (Polylane docs)
- Polylane documentation
- Polylane full content
Boris Tane is the founder of Polylane. He previously founded Baselime, observability for the future of the cloud, which Cloudflare acquired. At Cloudflare he built and led the Workers observability team.
Related
- Kubernetes OOMKilled (exit code 137): causes and fixes
Why Kubernetes reports OOMKilled with exit code 137, how to tell a limit kill from a node eviction or a plain SIGKILL, and how to size memory so it stops.
- Fix “context deadline exceeded” in Docker and fly deploy
What “context deadline exceeded” means in Docker and fly deploy, how to find the call that timed out, and the fixes for WireGuard, builders and daemons.
- Is It Safe to Give an AI SRE Read Access to Production?
Read access for an AI SRE is a sound first step if you scope it. The risks are secrets, customer data and exfiltration. Here are the controls and a checklist.
- Fix “Durable Object reset because its code was updated”
Why a deploy makes Cloudflare Durable Objects throw “reset because its code was updated”, and how to retry safely, keep clients connected and lose no state.
- Fix “remaining connection slots are reserved” in PostgreSQL
Why Postgres refuses new logins with “remaining connection slots are reserved”, how to find who holds the connections, and how to pool and cap them for good.